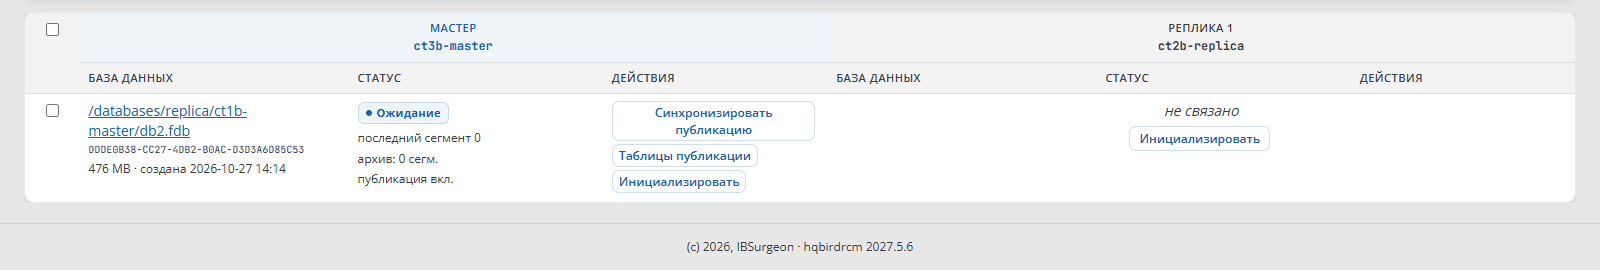
Administrator guide for the HQbird replication cluster: hqclusternode and hqbirdrcm (RCM). Installers: HQbird 2027 Download. Русская версия: на русском.
This guide describes how to install and use the HQbird replication cluster:
the hqclusternode nodes and the cluster manager hqbirdrcm (RCM).
This is a guide for the Firebird administrator. We assume that you know Firebird,
gfix and nbackup. You do not need to know the internal workings of a node.
What the cluster consists of
Component
How many
Where it runs
What it does
Firebird (HQbird)
one or more instances
on each database server
stores databases, writes replication segments
fbagent
one per Firebird instance
alongside Firebird
stops and starts Firebird at the request of a node
A node has a role: master or replica. Two nodes can run on a single
Firebird instance: a master node and a replica node.
In that case some databases of this Firebird are masters and others are replicas.
How it works
On the master, Firebird writes database changes to segments (replication
log files).
The master node sends the segments to the replica node over a secured channel (mTLS).
The replica node places the segments in the incoming segments folder. The replica’s Firebird
applies them to its copy of the database.
The master node itself transfers the first copy of the database to the replica. This is called
initialisation (reinit). It goes through nbackup, and the master keeps
running during this time.
The nodes send statistics to RCM. RCM shows the state of the cluster and
sends operator commands to the nodes.
How the cluster works: segments, initialisation, statistics and operator commands
Supported versions
Firebird / HQbird 5.0 and 4.0 — all features.
HQbird 3.0 and 2.5 — replication via the replconf plugin. There are no publications;
the set of tables is defined by filters. The differences are described in the “HQbird 2.5/3.0” boxes.
The major version of Firebird on the master and on the replica must match. Otherwise the replica
node will refuse initialisation.
Ports
Port
Who listens
Who connects
What for
7051
node
other nodes and RCM
node API, transfer of segments and database copies
7443
RCM
all nodes
receiving statistics from nodes
7444
RCM
operator
web interface and operator API. Installation via RCM (chapter 1.3): HTTPS on all addresses. Installation via HQCenter Admin or manually: HTTP, 127.0.0.1 only
7450–7459
fbagent, while the linking window is open
RCM
linking hosts (chapter 1.3)
13050
fbagent, 127.0.0.1 only
node on the same host
Firebird management
3050
Firebird
applications
normal database operation
If there are two nodes on one host (master and replica), the second node has a different port.
When installing via RCM, the second node gets port 7061. In other cases
you set the port yourself, for example 7052.
Port 13050 must not be exposed to the network. Port 7444 with HTTP (installation via
HQCenter Admin or manually) must not be either: connect to the RCM web interface
through an SSH tunnel (chapter 1). When installing via RCM, port 7444 runs over
HTTPS, and the installer opens it in the firewall.
The main rule: no fbagent, no changes
A node changes the replication configuration only through fbagent: it needs to
restart Firebird. If fbagent is unavailable, the node refuses any action
that changes the configuration. It does not work “partially”.
Terms
Term
Meaning
Segment
a replication log file with database changes
Publication
the list of master tables whose changes go into segments (Firebird 4/5)
Initialisation (reinit)
transfer of a copy of the database from the master to the replica via nbackup
Database GUID
the Firebird database identifier; RCM uses it to link the master and the replica
Peer
partner node: for a master, its replicas
Companion
the second node on the same Firebird instance (master and replica on one host)
Make regular, Promote to master, new GUID, services (switchover, failover), switchover checklist
All chapters use one example:
What
Value
node-a
master node, databases in /databases/master
node-b
replica node, databases in /databases/replica
RCM
a separate host (may also be one of the database servers)
database
employee.fdb
1. Installing nodes and hqbirdrcm
There are three installation methods:
Method
When to choose it
What you do yourself
Via HQCenter Admin (1.2)
the usual path: the HQCenter Admin update server is reachable, auto-updates are needed
you run the fbagent installation script, approve the request, describe the cluster
Via RCM, without HQCenter Admin (1.3)
there is no HQCenter Admin, but you need certificates, configuration and updates without manual work; up to 3 database servers
you install HQbird on each host, log in to RCM, and in Settings → Link hosts specify the host addresses
Manually (1.4)
no access to HQCenter Admin, closed network, special requirements
you install the files, create certificates, write node.json and rcm.json, register the services
Via HQCenter Admin and via RCM you do not install the nodes and RCM yourself. They are installed by
fbagent when you add it to the cluster (chapter 2). Certificates and
configuration are also created automatically.
Linux and Windows are described in a single chapter. The Windows differences are in the
“On Windows” boxes.
1.1. Requirements
On every database server:
Firebird / HQbird 5.0, 4.0, 3.0 or 2.5 (2.5 — Linux only).
fbagent alongside every Firebird instance. Without fbagent the node does not work.
Time synchronisation (NTP, chrony, w32time) on all servers and on the
RCM host. Restart and transfer windows, lag estimation and
the “node not responding” check depend on the clocks.
Free space for the segment archive and for replica initialisation (chapter 4).
Windows: administrator privileges, x64, Windows 10 / Server 2016 or newer,
64-bit Windows PowerShell 5.1. On Windows 10 and Server 2016–2022, 7-Zip is required.
Where RCM will run. One RCM is needed per cluster. It can be installed on any
server that can see all nodes, including on one of the database servers.
1.2. Installation via HQCenter Admin
Step 1. Run the fbagent installation script
The script installs Firebird (the HQbird build), fbagent, and registers fbagent on the
HQCenter Admin server. Choose the script matching your Firebird version: fb25, fb30, fb40,
fb50.
Linux (as root):
Command
sudo sh fbagent-fb50_known.sh --goafts <HQCenter-Admin-server> --enroll --cluster
There is no -Cluster parameter on Windows: fbagent runs as
LocalSystem and creates the cluster folders itself.
Main parameters:
Linux
Windows
Meaning
--goafts <name>
-Goafts
HQCenter Admin server to download from; the name is provided by your supplier
--enroll
-Enroll
register fbagent in HQCenter Admin (certificate request)
--cluster
—
create the /opt/hqclusternode and /opt/hqbirdrcm folders (only needed for fbagent 2.55.2 and older; harmless for newer versions)
--channel
-Channel
fbagent update channel, stable by default
--token
-Token
licence token: HQCenter Admin will approve the request automatically
--port
-Port
Firebird port
--yes
-Yes
do not ask questions (needed when there is no terminal)
For the full list of parameters, see the README of the fbagent installation script.
Step 2. Approve the fbagent request
With the --enroll parameter, fbagent sends a certificate request (CSR) to HQCenter Admin and
waits up to 30 minutes for approval. You can approve it as follows:
automatically — if the installation was run with a licence token (--token) and
the licence has a free slot;
in the HQCenter Admin panel — the CSR requests section, this
host’s request, the approve and sign button;
via the HQCenter Admin API — POST /v1/admin/csr-requests/{id}/approve.
If registration did not succeed (for example, the waiting time ran out), fbagent still
works, but the script exits with code 2. Run the script again with
the same parameters: only the registration will be repeated.
A few minutes after registration, fbagent installs HQ Monitor itself.
Step 3. Describe the cluster
Nodes and RCM appear once you add fbagent to the HQCenter Admin cluster. How to describe the
cluster is covered in chapter 2.
After saving the cluster:
Within 10 minutes fbagent receives the cluster from HQCenter Admin (after that it checks
for changes every 60 seconds).
The fbagent on the RCM host creates the cluster certificate authority (CA) and signs
the certificates of all nodes.
Each fbagent writes node.json or rcm.json for its cluster
members.
On the next product check (every 3 minutes) fbagent installs and
starts the services.
What is installed and where:
What
Linux
Windows
Master node
/opt/hqclusternode/master/, service hqclusternode-master-p<port>
<HQbird>\hqclusternode\master\, service HQClusterNode-master-p<port>
Replica node
/opt/hqclusternode/replica/, service hqclusternode-replica-p<port>
<HQbird>\hqclusternode\replica\, service HQClusterNode-replica-p<port>
RCM
/opt/hqbirdrcm/, service hqbirdrcm
<HQbird>\hqbirdrcm\, service hqbirdrcm
<port> is the Firebird port, for example 3050. A single fbagent can host no more than
one master node, one replica node, one RCM and one router
(hqclusternode router, from HQbird 2027.2.30, chapter 8.7).
On Windows. fbagent versions before 2.83.0 installed nodes in C:\hqclusternode and
RCM in C:\hqbirdrcm. If these folders exist, fbagent continues to
use them.
Updates
fbagent checks for new versions of the node and RCM every 3 minutes; the default
channel is stable. The replica node is updated first, then the master node.
If, after an update, the service fails to start or reports the wrong version,
fbagent rolls back to the previous version and blocks the new one. The list of blocks:
<fbagent folder>/update/<product>/blocked-versions.json. To try the
version again, delete its line from this file.
1.3. Installation via RCM (without HQCenter Admin)
The cluster is managed by RCM. Each host’s fbagent receives the cluster description from RCM,
the fbagent on the RCM host signs certificates, and the node and RCM are updated from
releases stored by RCM.
Limitations:
One cluster per RCM.
No more than 3 seats. A seat is a host that runs a master or replica node.
A master and replica on the same host count as one seat. A host that runs only RCM
does not take a seat. A fourth host produces the error seats_exceeded.
RCM does not update fbagent or Firebird. fbagent updates them itself and does not
touch replication.conf, node.json, rcm.json or certificates.
There are two methods:
Link hosts in RCM — the usual method. Three actions: the installer on
each host (RCM on one host, discovery mode on the others), logging in to
RCM, the Link hosts form.
Manually from the command line — join tokens and
fbagent --cluster-join. Needed when port 7450 is closed between hosts or
the pairing window has already closed.
Licence. The trial licence includes the cluster feature. After the trial
period, fbagent does not install a node or RCM if the licence lacks cluster.
It never blocks updates of already installed nodes and RCM. Without
HQCenter Admin, a floating licence stops working after online_check_days plus
grace days. Therefore install a bound licence on each fbagent:
Command
fbagent --license-request --out license_request.json
# send the file to the vendor and receive license.jsonfbagent --license-install license.json
Without a licence, the master stops sending segments (chapter 2.8).
Ports:
Port
Where
Who connects
7443
RCM host
fbagent and nodes of all cluster hosts
7444
RCM host
operator’s browser (RCM console, HTTPS)
7450 (on the second and subsequent fbagent host — 7451…7459)
host in discovery mode, while the pairing window is open
RCM on the RCM host
7051 (second node of the same fbagent — 7061)
node hosts
other nodes and RCM (1.4, step 7)
Link hosts in RCM
Example from scratch. Two Linux servers, the .run installer, linking,
registration, publication, initialisation and reinitialisation under load — with
screenshots and measurements: the guide hqbird2027-linux-cluster-guide.ru.md and
the runbook hqbird2027-linux-cluster-runbook.ru.md (goafts repository, documentation
folder).
Step 1. Install HQbird on each host
Install HQbird with the full installer on each database server. Do not register with
HQCenter Admin (--enroll).
By default the installer does not configure a cluster. It places the node
and RCM programs in the fbagent folder (update/<product>/staged/), but does not install RCM, does not open the pairing
window and does not open the cluster ports in the firewall. The cluster
is enabled by two parameters:
Command
sudo sh hqbird2027-fb50-linux-<version>.run --rcm on # RCM hostsudo sh hqbird2027-fb50-linux-<version>.run --cluster-pairing on # other hosts
--rcm on — on one host, where the cluster’s RCM will run. The installer:
creates this host’s cluster (fbagent --cluster-init), the cluster name is the
host name;
installs and starts RCM, the RCM console runs over HTTPS on port 7444;
creates the first RCM administrator rcmadmin with a random password;
opens ports 7443, 7444 and node port 7051 in the firewall.
--cluster-pairing on (discovery mode) — on each other host.
The installer opens fbagent’s pairing window for 24 hours: port 7450 and
node port 7051. While the window is open, an RCM from the network can invite this host into
its cluster. fbagent starts listening on port 7450 within a minute.
Without these parameters the installer asks itself: in the text
interface this is the Cluster page, with --no-tui — two questions.
The default answer is “no”. --yes without cluster parameters also answers
“no” to both questions.
At the end the installer prints the lines RCM: and Pairing:. On the RCM host:
text
RCM:        https://10.0.0.7:7444 (cluster db1)
CA hash:    sha256:7cfc1d4b…032d2582
Login:      rcmadmin
Password:   in /opt/hqbird/fbagent-fb50/clusterca/db1/rcm-initial-password (read it with sudo; RCM asks for a new one at the first login)
Pairing:    not needed: this agent runs the RCM; other agents link through it
On another host:
text
RCM:        off; turn it on in HQbird Monitor or with fbagent --cluster-init <id>
Pairing:    port 7450 open until 2026-11-17T17:49:18Z (fingerprint sha256:0439e44a…91a2f9b9); an RCM may invite this host
There is no password in the output: it is in the file from the Password: line. Write down
the fingerprint of each host in discovery mode.
Cluster parameters in the Linux installer:
Parameter
What it does
--rcm on|off
install RCM and create a cluster on this host; default off
--cluster-pairing on|off
discovery mode: open the pairing window for 24 hours; default off
--pairing-port N
pairing port of the new fbagent, 7450–7459; default first free
--rcm-password-file F
RCM administrator password from the first line of file F, instead of random
--cluster-id ID
cluster name ID instead of the host name (with --rcm on)
--cluster-node on|off
install the node program; default on
--rcm-allow A,B
only these RCMs may invite this host: address, CIDR network or name
The first fbagent on a host gets pairing port 7450 and node ports 7051 and
7061. The second instance on the same host — 7451, 7052 and 7062.
RCM and the pairing window can be enabled later, without the installer: in HQ Monitor,
the Clusters page, or with commands as the fbagent user:
Command
cd <fbagent folder> # /opt/hqbird/fbagent-fb50sudo -u firebird ./fbagent --cluster-init <name> # RCM host; open ports 7443 and 7444 yourselfsudo -u firebird ./fbagent --cluster-pairing on # window for 24 hourssudo -u firebird ./fbagent --cluster-pairing off
sudo -u firebird ./fbagent --cluster-pairing status
Old installers (fbagent before 3.1.0) do not ask about the cluster: they
install RCM on every host and open the pairing window everywhere. You need the RCM of
one host; the RCMs of other hosts stop themselves after linking.
On Windows. The same two choices exist in the Windows installer: the parameters
/RCM and /DISCOVERY.
Step 2. Log in to RCM
Open the address from the RCM: line of the RCM host (https://<host>:7444). Log in with
the login rcmadmin and the password from the file in the Password: line. RCM immediately asks for a
new password (1.5).
Step 3. Link the hosts
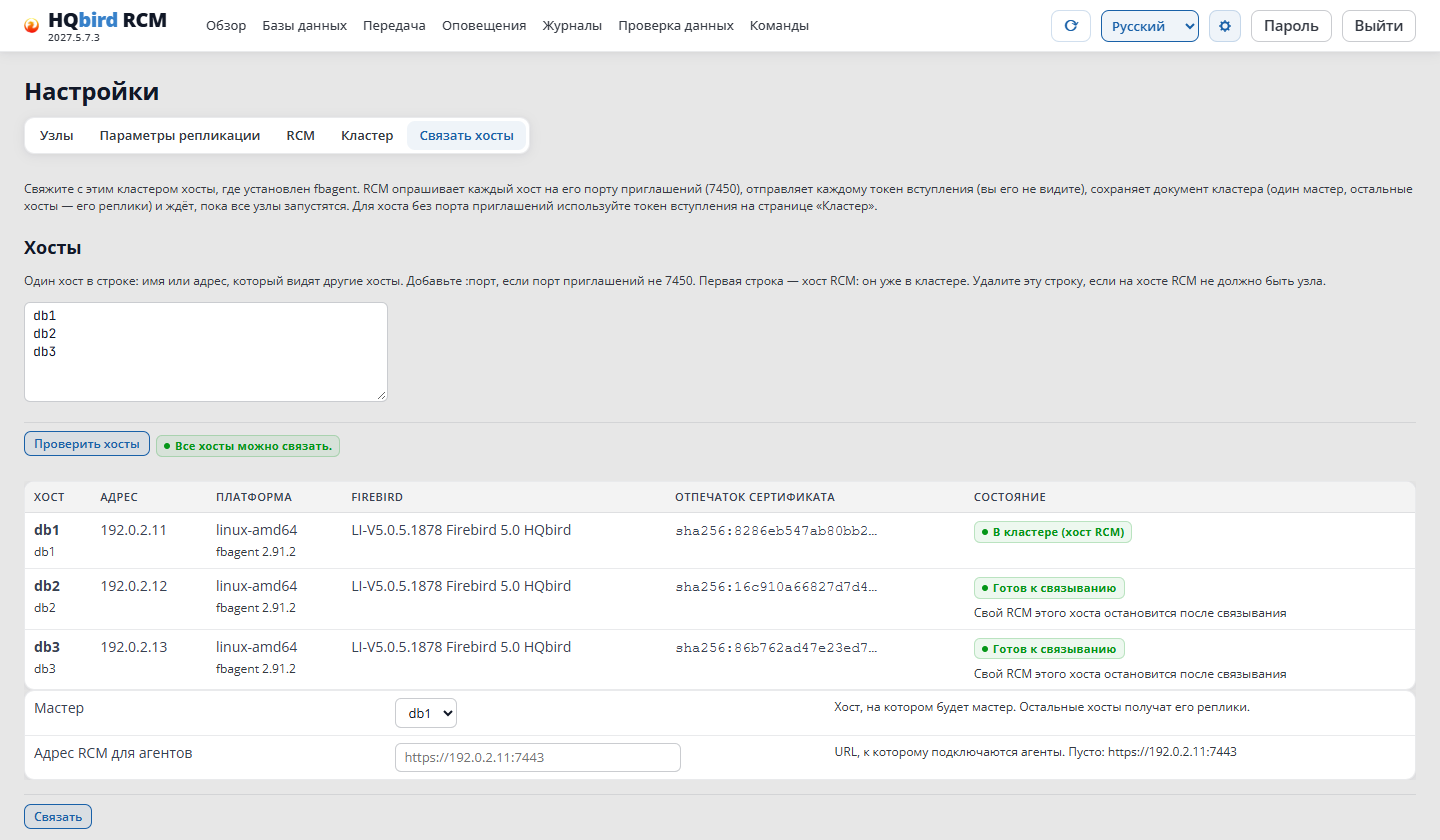
In RCM open Settings → Link hosts.
In the Hosts field enter the addresses or names of the hosts, one per line.
The first line is the RCM host, it is already in the cluster.
Click Check hosts. RCM probes the pairing ports
7450–7459 of each host and shows the platform, Firebird version,
fingerprint and state. The RCM host does not need a pairing window. Compare
the fingerprints with the installer output (the Pairing: line).
Select the Master (default first host) and click Link.
Link hosts: check result
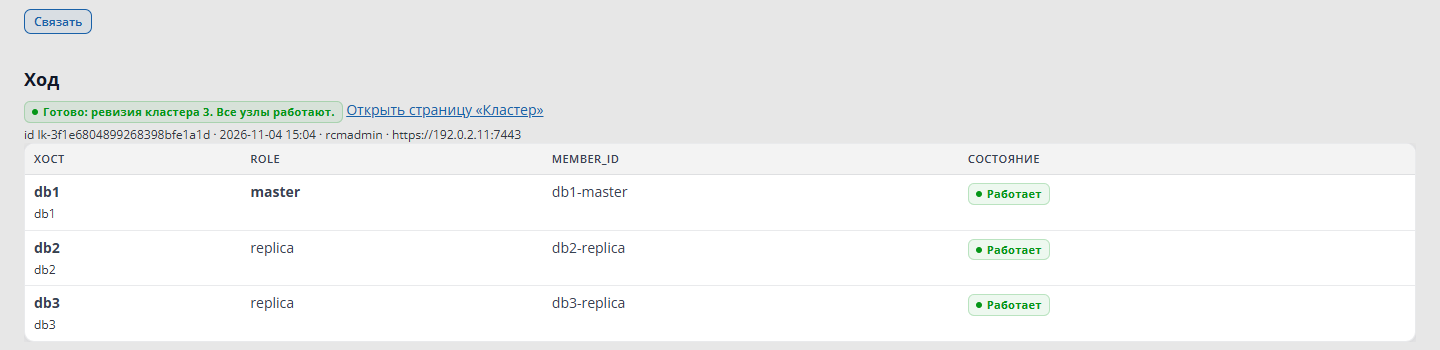
RCM asks for confirmation and shows progress in the Progress section. When all nodes
are running, it says “Done” and shows the cluster revision number:
Link hosts: all nodes running
The same from the command line:
Command
cd /opt/hqbirdrcm
exportRCM_USER=rcmadmin RCM_PASSWORD='<password>'./hqbirdrcm cluster link -hosts db1,db2,db3 -master db1
What happens next:
RCM sends an invitation to each free host.
The host’s fbagent joins the cluster and closes the pairing port. If the
host has its own RCM without nodes, fbagent stops and disables it, and
moves its empty cluster to cluster/left/ in the fbagent folder.
RCM saves the cluster: node <host>-master on the master, <host>-replica on
the other hosts, port 7051, master → replica links.
Each host’s fbagent installs and starts the node. RCM waits until all nodes
are running and shows Running for each host.
Host states after Check hosts:
State
What to do
Ready to link
nothing. If below it says “This host’s own RCM will stop after linking” — that is normal
In cluster
the host is already in this cluster
Error unreachable
port 7450 is closed: the pairing window is off (as by default) or the 24 hours have passed. Right after installation wait a minute and click Check hosts again. Otherwise open the window (--cluster-pairing on) and check the firewall
Error in_other_cluster
the host is in another cluster
Error claimed
another RCM is linking this host right now
Error seats_exceeded
more than 3 seats
Releases. fbagent installs the node only from RCM. RCM takes signed
releases from its import/ folder (next to rcm.json) at startup and every
5 minutes. The installer puts the RCM host’s releases there, and fbagents of other hosts
download the release for their platform themselves. The list of releases is at the bottom of the
Link hosts page. A release can also be imported manually (step 5 below).
Manually from the command line
Order: steps 1–3 on the RCM host, step 4 on each other host, steps 5–6 in RCM.
Step 1. Install HQbird with fbagent
Install HQbird on each database server and on the RCM host with the full installer.
On the RCM host you can specify --rcm on right away (then step 3 is not needed). On other
hosts do not specify cluster parameters: by default there is no RCM and no pairing
window. Do not register with HQCenter Admin (--enroll).
On the RCM host the installer leaves the RCM program in the fbagent folder
(update/hqbirdrcm/staged/). Without it step 3 fails with the error
no hqbirdrcm to install.
Step 2. Install the bound licence
As at the beginning of the section, “Licence”.
Step 3. Create the cluster on the RCM host
If the installer has already created the cluster (--rcm on: an RCM: line with an address in its
output), skip this step.
Run the command as the fbagent user (on Linux — firebird), not as
root: otherwise the CA files and rcm.json will be owned by root.
On Windows (PowerShell as administrator):
.\fbagent.exe --cluster-init shop-prod --address 10.0.0.7
shop-prod — cluster name: lowercase Latin letters, digits and -.
--address — the address of the RCM host by which other
hosts connect to it. Can be repeated several times. Without the parameter, the host’s addresses and name
are used.
The command:
creates the cluster CA and the agent CA (in the fbagent folder, clusterca/<name>/);
writes the RCM certificate, rcm.json and cluster-init.json to the RCM folder;
installs RCM and registers the hqbirdrcm service. On Linux the service runs as
a separate user hqbirdrcm;
switches fbagent to RCM (cluster.source = rcm) and restarts it;
prints the RCM address and CA fingerprint:
Code
Cluster:    shop-prod
RCM URL:    https://10.0.0.7:7443
CA hash:    sha256:9f86d0...
Write down RCM URL and CA hash: they are needed on the other hosts. Re-running
for the same cluster is safe: the CA and keys stay the same.
Log in to RCM immediately and change the rcmadmin password (1.5).
On Linux. The user hqbirdrcm is in the fbagent group. RCM reads
rcm.json through this group, but cannot write it. Therefore Settings → RCM does not save changes (error
rcm_config_read_only). Edit rcm.json on the host as the fbagent user
and restart RCM.
Step 4. Connect fbagents of other hosts
On the RCM host create a join token for each fbagent: in RCM
Settings → Cluster, the Create join token button. Or from
the command line:
Command
cd /opt/hqbirdrcm
exportRCM_USER=rcmadmin RCM_PASSWORD='<password>'./hqbirdrcm cluster join-token -note db2
The token is valid for 24 hours, for one fbagent only and only once. RCM
shows it once, together with a ready-made command.
On the node host run this command as the fbagent user:
Instead of --token-file you can use --token <token>. On Windows — the same with
.\fbagent.exe in PowerShell as administrator.
fbagent verifies the RCM CA by fingerprint. If the fingerprint does not match, it
stops and writes nothing. Then fbagent receives its certificate
(90 days, renewed automatically) and restarts. A connected fbagent is visible in
RCM in the Agents table. While it has no members, nothing is installed on the host.
Step 5. Import releases into RCM
fbagent takes the node and RCM only from RCM. If the required release is not in the
Releases in mirror list (Settings → Link hosts), import each product
(hqclusternode, hqbirdrcm) for each platform of your hosts
(linux-amd64, windows-amd64). The release file and the .sig signature are provided by
the vendor.
RCM looks for the signature in <file>.sig, or specify it with -sig. Without
a valid vendor signature RCM will not accept the file.
A new release replaces the previous one. No RCM restart is needed.
fbagent checks for new versions every 3 minutes. The update order and
locking are as via HQCenter Admin (1.2, “Updates”).
Step 6. Describe the cluster
Set the members and links in RCM, Settings → Cluster (chapter 2.3). After
saving, fbagent installs the nodes in the same way as via HQCenter Admin (1.2, step 3): it writes
certificates, node.json and rcm.json, installs and starts the services.
Ports — at the beginning of the section.
1.4. Manual installation
Step 1. Install HQbird with fbagent
Install HQbird on every database server (with the same script, but without --enroll, or with the full HQbird installer). Verify that fbagent is running.
Note down three values from fbagent’s agent_config.json. They are needed for node.json:
fbagent field
node.json field
Example
local_api.listen
firebird.fbagent_url
http://127.0.0.1:13050
local_api.token
firebird.fbagent_token
—
local_api.instance_id
firebird.instance_id
—
Checking fbagent (the response is the Firebird instance’s JSON):
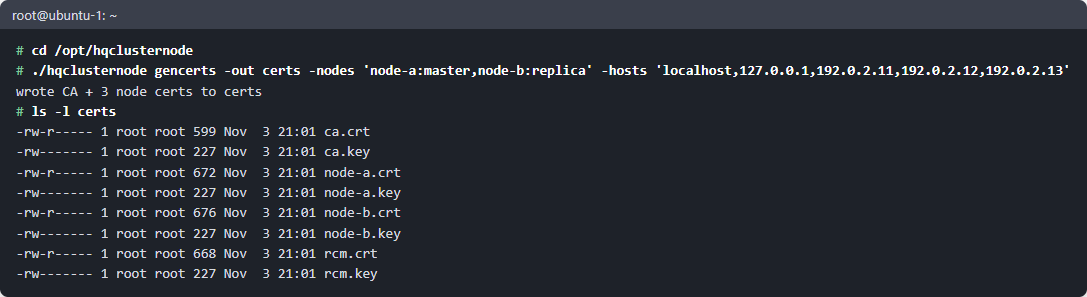
The command creates ca.crt and ca.key, node-a.crt/.key, node-b.crt/.key and rcm.crt/.key. In -hosts, list all names and addresses by which the participants will be connected to.
gencerts and the files it created
ca.key is the CA key. Do not copy it to the hosts; store it separately.
A new node is added later with -add: it signs the pair with the same CA, and the other files are left unchanged:
Certificates are valid for 90 days. gencerts -out certs -list shows the expiry dates, and gencerts -out certs -renew renews them with the same key. Copy the new .crt to its host: the node will pick it up without a restart.
Copy ca.crt and only its own certificate and key to each host.
Step 4. Write node.json
One file per node. Example for the master (node-a):
json
{"node_id":"node-a","role":"master","listen_addr":":7051","rcm":{"url":"https://<ip-rcm>:7443","ca_cert":"certs/ca.crt","client_cert":"certs/node-a.crt","client_key":"certs/node-a.key"},"firebird":{"root":"/opt/firebird","user":"SYSDBA","password":"<SYSDBA password>","port":3050,"replication_conf":"/opt/firebird/replication.conf","replication_log":"/opt/firebird/replication.log","firebird_log":"/opt/firebird/firebird.log","fbagent_url":"http://127.0.0.1:13050","fbagent_token":"<local_api.token>","instance_id":"<local_api.instance_id>","service_name":"<Firebird service name>"},"windows":{"restart_window":"22:00-05:00","transfer_window":"23:00-05:00"},"peers":[{"node_id":"node-b","url":"https://<ip-node-b>:7051","compress":"zstd"}]}
The replica node (node-b) has the same file, but with "role": "replica", its own certificates, and the master node-a in peers.
Main fields:
Field
Value
node_id
node name; the same in the certificate, rcm.json and the peers of other nodes
role
master or replica
listen_addr
the node API address; a second node on the same host uses a different port (:7052)
rcm.url
the address for receiving RCM statistics; none — no RCM
firebird.*
the Firebird and fbagent of this instance; the fbagent values must match exactly
firebird.auto_restart
whether the replica node may restart Firebird itself: auto (default), never, always
windows.restart_window
the Firebird restart window; for the master the default is 22:00-05:00, for the replica it is always
windows.transfer_window
the window in which initialisation runs at full speed
peers
for the master — its replicas, for the replica — its master
databases
the databases folder; better not to write it by hand but to set it via RCM (chapter 3)
The remaining fields have default values. The node will not start if the fbagent fields are not set.
Protect the file: it contains the password and the token.
Command
chmod 600 /opt/hqclusternode/node.json
On Windows. Write paths in JSON format: "C:\\HQbird\\replication.conf".
service_name is the Windows service name for Firebird.
url — the node address as seen by the RCM host. https only.
host — the Firebird instance label. A master node and a replica node with the same label run on the same Firebird (companion, needed to promote a replica to master, chapter 8). One label — no more than one master and one replica.
Relative paths are resolved from the rcm.json folder.
Step 6. Register the services
Start order: RCM first, then the replicas, then the master.
cd /opt/hqclusternode
sudo ./hqclusternode svc install -config /opt/hqclusternode/node.json -certs /opt/hqclusternode/certs
sudo ./hqclusternode svc start -config /opt/hqclusternode/node.json
systemctl status hqclusternode-master-p3050
svc install creates the service hqclusternode-<role>-p<port> running as the firebird user. If the Firebird folder is owned by root, the command grants the firebird group write access to it (with the sticky bit) and prints every change: the node needs to replace replication.conf.
For svc start, svc stop and svc uninstall, specify the same node.json: the service name is derived from the role and the Firebird port.
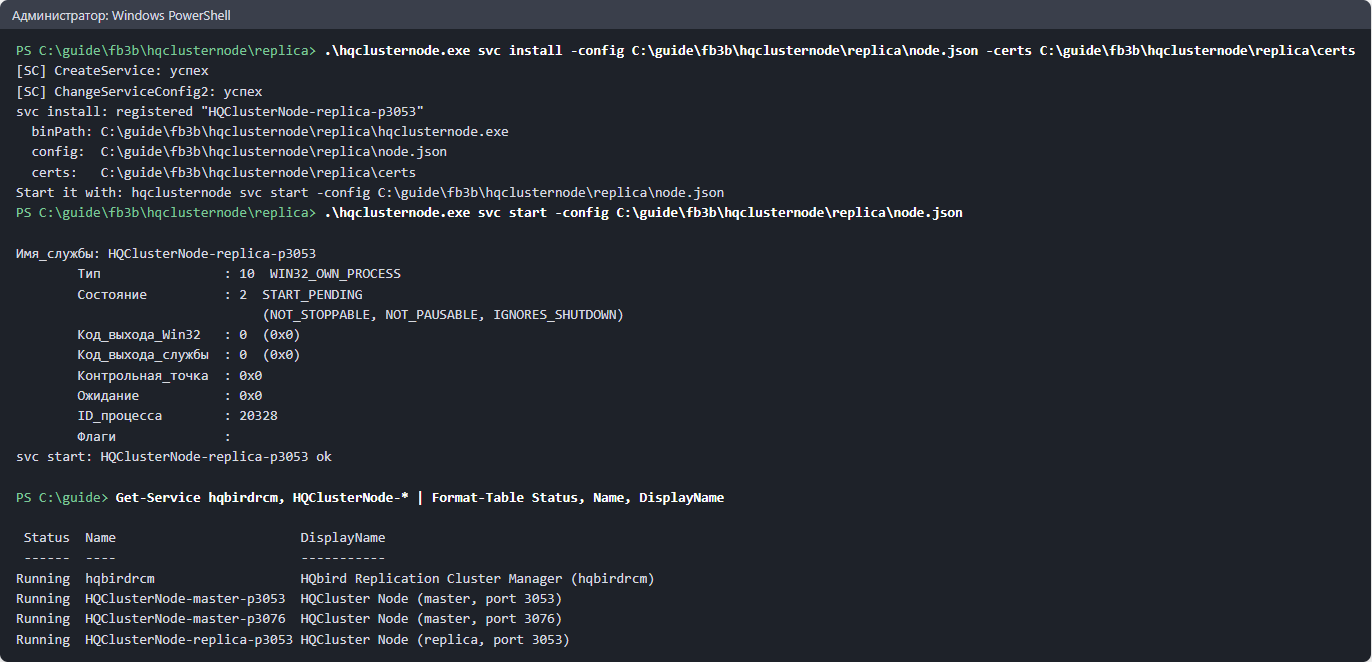
On Windows (PowerShell as administrator):
Command
cd C:\hqclusternode
.\hqclusternode.exe svc install -config C:\hqclusternode\node.json -certs C:\hqclusternode\certs
The service HQClusterNode-<role>-p<port> runs as LocalSystem, starts automatically and restarts after a failure. The node service does not depend on the Firebird service. If the node was installed with version 2027.1.2–2027.1.9, remove the dependency once:
.\hqclusternode.exe svc fix-deps -config C:\hqclusternode\node.json.
svc install and svc start on Windows
Step 7. Open the ports
On the node host, allow inbound connections on 7051 (the listen_addr port) from the other nodes and from RCM. On the RCM host, allow inbound connections on 7443 from all nodes. Do not expose ports 7444 and 13050 externally.
Example ufw on the node host:
Command
sudo ufw allow from <ip-rcm> to any port 7051 proto tcp
sudo ufw allow from <ip-partner-node> to any port 7051 proto tcp
Manual update
Stop the service, replace the program, start the service:
The configuration and certificates are not changed by this.
1.5. First login to RCM
The address and password depend on how RCM was installed.
How RCM was installed
Address
Login and password
By the HQbird installer or fbagent --cluster-init (1.3)
https://<RCM host>:7444 from any computer
rcmadmin and the password printed by the installer (or your own from --rcm-password-file)
Via HQCenter Admin (1.2) or manually (1.4)
http://127.0.0.1:7444, only on the RCM host
rcmadmin, password strong password (with a space)
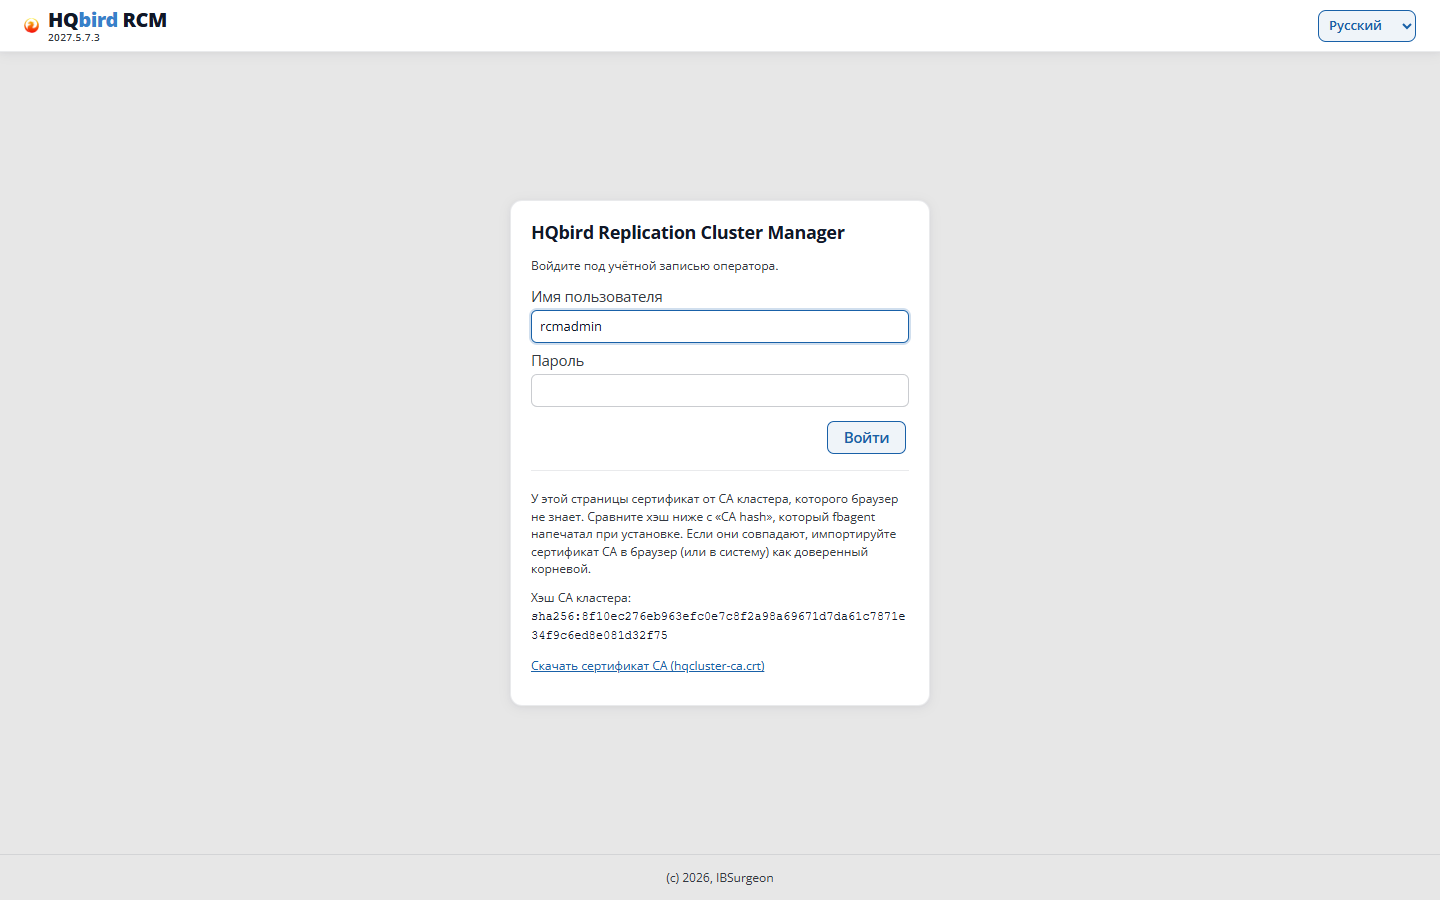
HTTPS (1.3). The RCM certificate is signed by the cluster CA, which the browser does not know, so it warns you. On the login page RCM shows the CA fingerprint. Compare it with the CA hash printed by the installer, and import the CA into the browser or into the system as a trusted root: the Download CA certificate link on the login page (https://<RCM host>:7444/ca.crt, file hqcluster-ca.crt). To make RCM listen only on localhost, set "operator_addr": "127.0.0.1:7444" in rcm.json and restart RCM.
HTTP (1.2, 1.4). From another computer, connect via an SSH tunnel:
Command
ssh -L 7444:127.0.0.1:7444 <rcm-host>
Then open http://127.0.0.1:7444 in your browser.
RCM login page
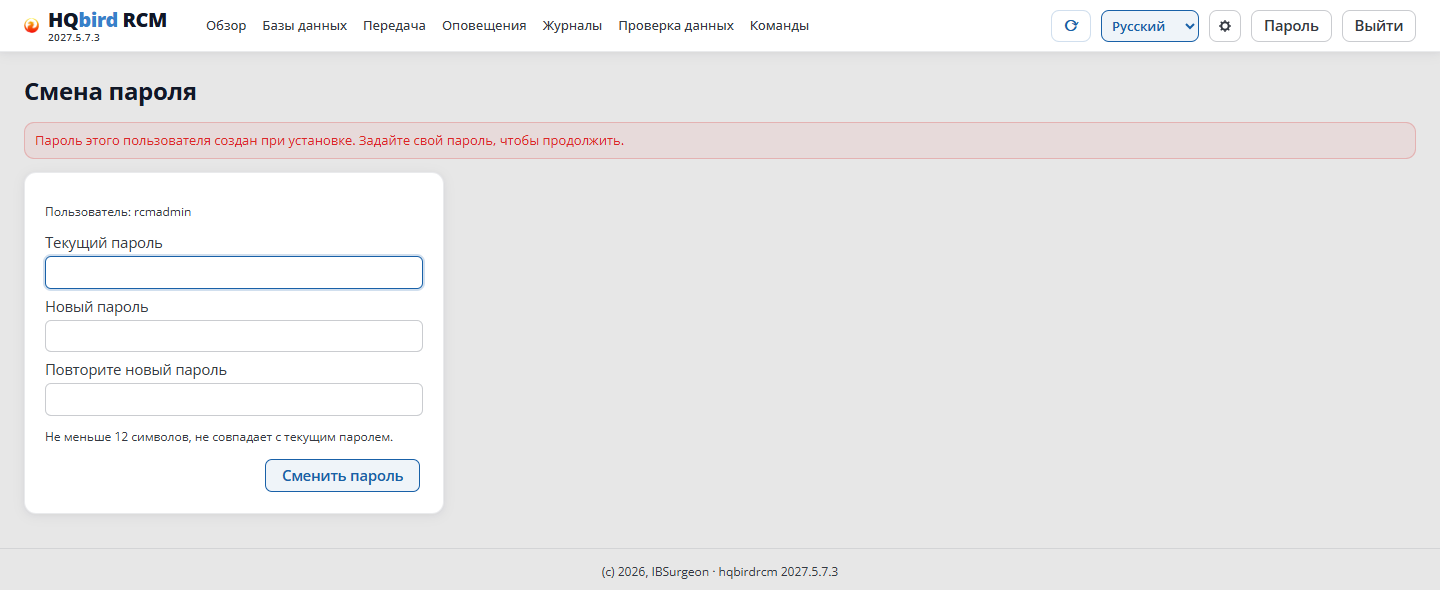
Generated password. RCM asks you to change it on first login: until you change it, the other pages will not open. Change the strong passwordimmediately (the Password link in the header).
Changing the password on first login
Language. Select Russian in the language list in the page header (it is also available on the login page). If you do not select one, the language is taken from the browser.
Changing passwords and new users
Each user changes their own password: the Password link in the page header. You need the current password and a new one of at least 12 characters. After the change, that user’s other sessions are closed.
If the installer generated a password, it is written to the file clusterca/<name>/rcm-initial-password in the fbagent folder. After the password is changed, fbagent deletes this file itself. Do not delete the initial-admin.json file in the RCM folder: it contains only a hash. If the users file is lost and this file is absent, RCM will create a user with the default password.
New users. There is no users page in the interface. Users are stored in the file rcm-data/users.json. The password is stored as an HA1 hash: MD5("<name>:hqbirdrcm:<password>").
Restart RCM immediately: it reads the file only at startup. When a password is changed in the interface, RCM rewrites the file from memory, and any edits it has not yet read will be lost.
Without a role field, a user has all permissions. Since HQbird 2027.2.31 there is a "role": "viewer" role: view only, any modification request gets 403.
1.6. How to verify the installation
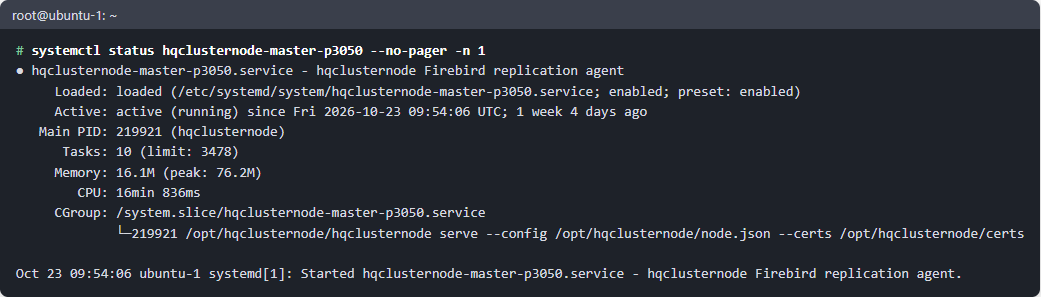
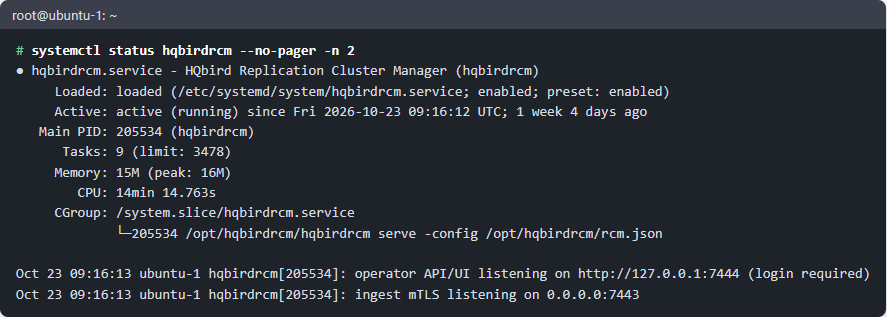
The node and RCM services are running and are not restarting in a loop:
systemctl status hqclusternode-master-p3050, systemctl status hqbirdrcm.
systemctl status of the node
systemctl status of RCM
RCM responds (without a password): curl http://127.0.0.1:7444/healthz. When
installed via RCM (1.3), the console works over HTTPS:
curl -k https://127.0.0.1:7444/healthz.
In RCM, the Overview page shows all nodes, with no “not
responding” marker.
From the command line on the RCM host:
Command
exportRCM_USER=rcmadmin RCM_PASSWORD='<password>'./hqbirdrcm nodes
./hqbirdrcm status
The cluster via RCM: Settings → Cluster, the State section — each
member has applied the latest revision and reports no error. From the command
line: ./hqbirdrcm cluster status.
1.7. Logs
What
Where
Node log
<node.json folder>/logs/node-YYYYMMDD.jsonl
Node service output (Linux)
journalctl -u hqclusternode-<role>-p<port>
RCM service output (Linux)
journalctl -u hqbirdrcm
Firebird replication log
firebird.replication_log from node.json
Logs from any node without SSH
RCM, Logs page
1.8. Common errors
What you see
Cause
What to do
The node does not start: an error about fbagent_url, fbagent_token or instance_id
fbagent is not running or the values do not match agent_config.json
check fbagent with the curl command from 1.4, step 1
The installation script exited with code 2
the fbagent request was not approved in time
approve the request and run the script again
Nodes do not appear via HQCenter Admin
fbagent is not in the cluster, or the cluster has not been obtained yet
check the cluster (chapter 2), wait up to 10 minutes
The node in RCM is “not responding”
port 7051 is closed, the url in rcm.json is incorrect, the address is not in the certificate
check the ports and the certificates’ -hosts
No sign-in to RCM: “Too many failed sign-in attempts”
10 failed sign-ins within 5 minutes
wait a few minutes
The new version will not install
the version is in blocked-versions.json
remove the version line from the file
--cluster-init: no hqbirdrcm to install
the installer did not leave the RCM program
install HQbird with the full installer (1.3, “Manually”, step 1)
the token has already been used, is older than 24 hours, or has been revoked
create a new token (1.3, “Manually”, step 4)
--cluster-join: hostname_conflict
the cluster has an fbagent with the same hostname and different addresses
give the hosts different names
--cluster-join: this agent is in cluster … from goafts
fbagent is already in the HQCenter Admin cluster
remove it from the HQCenter Admin cluster
The node will not install via RCM
RCM has no release for this platform
hqbirdrcm release list, import the release (1.3, “Manually”, step 5)
2. Cluster configuration
In this chapter you define which nodes are in the cluster and which master sends
segments to which replica. Then you configure the RCM nodes and users.
Relationships are defined in one of three ways:
Nodes installed
Where relationships are defined
Section
via HQCenter Admin
in HQCenter Admin: the Clusters page of HQ Monitor or the HQCenter Admin API
2.2
via RCM, without HQCenter Admin
in RCM: Settings → Cluster, hqbirdrcm cluster or the Clusters page of HQ Monitor
2.3
manually
in RCM: Settings → RCM and Settings → Nodes
2.3
On nodes installed via HQCenter Admin or via RCM, change relationships only in
the cluster description. fbagent overwrites node.json and rcm.json according to
the cluster description. Editing relationships in Settings → RCM or Settings → Nodes
of RCM is rejected (409 cluster_managed). Earlier versions of RCM accepted it, but it
was lost.
2.1. Roles and schemes
Each node has one role: master or replica. Two nodes — a master and a replica — can run on a single Firebird instance.
Supported schemes:
Code
1 → 1        node-a (master) ──▶ node-b (replica)

1 → N        node-a ──▶ node-b
                    └─▶ node-c

N → 1        node-a ──┐
                      ├─▶ node-b    (one replica for several masters)
             node-x ──┘

Both nodes   host-1: node-1m (master) + node-1r (replica)  ← one Firebird
on a host    host-2: node-2m (master) + node-2r (replica)  ← one Firebird
             node-1m ──▶ node-2r,  node-2m ──▶ node-1r
The link always goes from the master to the replica. RCM links the master’s database to its replica by database GUID, not by node name.
Companion. A master node and a replica node on the same Firebird instance are companions. Promotion of a replica to master (chapter 8) works only for such a pair. In rcm.json the pair is marked by an identical host value.
2.2. Links via HQCenter Admin
Where to describe a cluster
HQ Monitor, Clusters page (administrators only; configuration delivery must be enabled). The usual way.
HQCenter Admin API:POST /v1/admin/clusters and
PUT /v1/admin/clusters/{id}. The HQCenter Admin panel has no
clusters page.
``
Steps on the Clusters page
Enter a New cluster id (lowercase Latin letters, digits and -) and click
Create.
Add members (Members). For each one specify:
the host’s fbagent;
the role: master, replica or rcm;
the host addresses;
the port: for a node — 7051 (a second node on the same host — e.g. 7052),
for RCM — the statistics intake port 7443.
Add links (Replication links) from the master to the replica.
Click Validate, then Save.
If another administrator changed the cluster at the same time, the page will ask
you to reload the cluster and repeat the change.
Rules
An fbagent can belong to only one cluster.
On a single fbagent — no more than one master, one replica, one RCM and
one router. The router (role router, from HQbird 2027.2.30) has no links and
does not take up a licence seat (chapter 8.7).
A cluster has exactly one RCM. The fbagent on the RCM host runs the cluster’s
certificate authority (CA).
The member name (member_id) — Latin letters, digits, -. The name, fbagent and role
of a member cannot be changed. To move a member to another host, create a
new member with a new name. Do not use the old name again.
Every replica must have a link to the master.
HQCenter Admin builds the node address itself: https://<first address>:<port>.
HQbird 2.5/3.0: set the cluster’s replconf_valid_till date
(YYYY-MM-DD) — the replconf plugin configuration is valid until that date.
Example via the API
json
{"contract":1,"cluster_id":"shop-prod","name":"Shop","pki":"managed","cert_validity_days":90,"renew_before_days":30,"members":[{"member_id":"db1-m","agent_id":"<fbagent of host 1>","role":"master","addresses":["db1.lan"],"listen_port":7051},{"member_id":"db1-rcm","agent_id":"<fbagent of host 1>","role":"rcm","addresses":["db1.lan"],"listen_port":7443},{"member_id":"db2-r","agent_id":"<fbagent of host 2>","role":"replica","addresses":["db2.lan"],"listen_port":7052}],"links":[{"from":"db1-m","to":"db2-r"}]}
Create: POST /v1/admin/clusters (the document can be sent together with
members). Replace the whole document: PUT /v1/admin/clusters/{id}.
PUT requires the header If-Match: <revision> (the revision is provided by GET and ETag).
Without the header — 428, with an old revision — 409, with an error in the document —
422 with a list of errors.
POST /v1/admin/clusters/{id}/validate validates the document without saving.
GET /v1/admin/clusters/{id}/status shows the state of members and certificate
expiry dates.
What happens after saving
Each member’s fbagent receives the cluster. Within the cluster — a check every
60 seconds (the fbagent on the RCM host — every 30 seconds). Outside a cluster, an fbagent
learns about the cluster on its next configuration poll. If that poll does not
reach the server, the check runs every 10 minutes.
Each fbagent creates a key and sends a certificate request. The fbagent on the
RCM host signs it. RCM signs its own certificate without a request.
fbagent writes to node.json: name, role, address, peers (from the links), the
RCM address, certificate paths, Firebird and fbagent data. To rcm.json: the list of
nodes (nodes), the list of routers (routers), the statistics intake address and the
certificate paths. fbagent does not touch the other fields of the files.
fbagent installs and starts the services (chapter 1).
Changing a cluster:
What changed
What fbagent does
only the peers of a running node
passes them to the node without a restart
other fields of a node
stops the node, writes the file, starts the node — within the node’s windows.transfer_window (not set — immediately)
rcm.json
restarts RCM immediately
certificates or CA
restarts the service
a member is removed
stops and removes the service; cluster-managed.json → cluster-removed.json, the program → *.removed; the configuration, certificates and data remain
After a node is removed, its section
# BEGIN managed-by:<name> … # END … remains in the shared replication.conf. Delete it manually and restart
Firebird via RCM.
Approving cluster certificates
By default the fbagent on the RCM host signs requests itself (auto). Manual approval
can be enabled. Commands on the RCM host:
Command
fbagent --cluster-ca-approval manual # or autofbagent --cluster-status # this fbagent's membership in the cluster (JSON)fbagent --cluster-ca-approve <request_id>
In manual mode, a new member or a new key waits for approval. Renewal of a
certificate with a known key is signed automatically.
2.3. Links via RCM
RCM cluster (without HQCenter Admin)
If the cluster was created by the HQbird installer or by the fbagent --cluster-init command
(chapter 1.3), the cluster description is stored by RCM. The easiest way to add hosts is on the
Settings → Link hosts page (chapter 1.3, “Link hosts in RCM”):
RCM creates the members and links itself. The rules are the same as in HQCenter Admin (2.2, “Rules”), plus:
in RCM there is one cluster; the rcm member always exists and cannot be deleted;
no more than 3 seats (hosts with master or replica nodes), otherwise the error
seats_exceeded occurs;
a member can only be added on an fbagent that has connected to RCM
(chapter 1.3: “Link hosts” or “Manually”, step 4).
Steps on the Settings → Cluster page:
In the Agents table, click Add member in the fbagent row.
Specify the role (master, replica or router), member_id, addresses and port.
The page suggests the name <host>-<role> and the port: 7051 for the first fbagent node,
7061 for the second. A port that is already taken by another member of the host is rejected by RCM. The
fbagent addresses are buttons: click to add an address.
In the Links section, click Add link from the master to the replica.
Click Validate: RCM will show errors and warnings.
Click Save. The page will show the list of changes and ask for
confirmation. If members are being deleted, the window is red.
Before saving, the changes exist only on the page (the “Not saved” label). If
someone saved the cluster at the same time, the page will offer to reload it.
If only RCM fields changed (revision, CA, commissions), the page will save
your change itself.
Other sections of the page:
Section
What is there
header
cluster name, revision, cluster CA and agent CA; the Export button for the old CA
Connection tokens
create a token for a new fbagent, revoke an unused one
JSON document
the whole document in a text field; Validate and Save use it
Keys and CAs
commissions: new member key (rekey), new cluster CA (rotate_ca), new agent CA (rotate_agent_ca); unavailable when there are unsaved changes
State
the revision each member has applied, certificate expiry, service, last error
From the command line on the RCM host:
Command
exportRCM_USER=rcmadmin RCM_PASSWORD='<password>'./hqbirdrcm cluster show > c.json # document with revision# edit c.json./hqbirdrcm cluster validate -f c.json # validate without saving anything./hqbirdrcm cluster apply -f c.json # save (If-Match = revision from the file)./hqbirdrcm cluster agents # connected fbagents and their members./hqbirdrcm cluster status # what the fbagents reported
The document format is as in 2.2, “Example via API”. apply with an old revision
gets 409: run show again. RCM keeps the last 20 revisions in
rcm-data/cluster/history/.
HQ Monitor. The Clusters page also works with RCM. On the RCM host,
HQ Monitor accesses RCM through that host’s fbagent, with the fbagent
certificate: the RCM user and password are not needed. In the RCM audit log such
actions are recorded as agent:<id> (<user>). Another way, for earlier
RCM versions: in the HQ Monitor configuration set rcm_admin_url
(http://127.0.0.1:7444), rcm_admin_user (the RCM user) and
rcm_admin_password_file (a file with its password).
After saving, everything proceeds as via HQCenter Admin (2.2, “What happens after
saving”). RCM re-reads nodes in rcm.json itself, without a restart.
Remove an fbagent from the cluster: delete its members and save, then
click Revoke in the Agents table (or
./hqbirdrcm cluster revoke -agent <id>). To bring it back, a new
token is needed. After revocation the fbagent (since version 3.1.0) leaves the cluster
itself: it stops its nodes and deletes the cluster data. The same is done on a
node host by the fbagent --cluster-leave command. On the RCM host it is rejected.
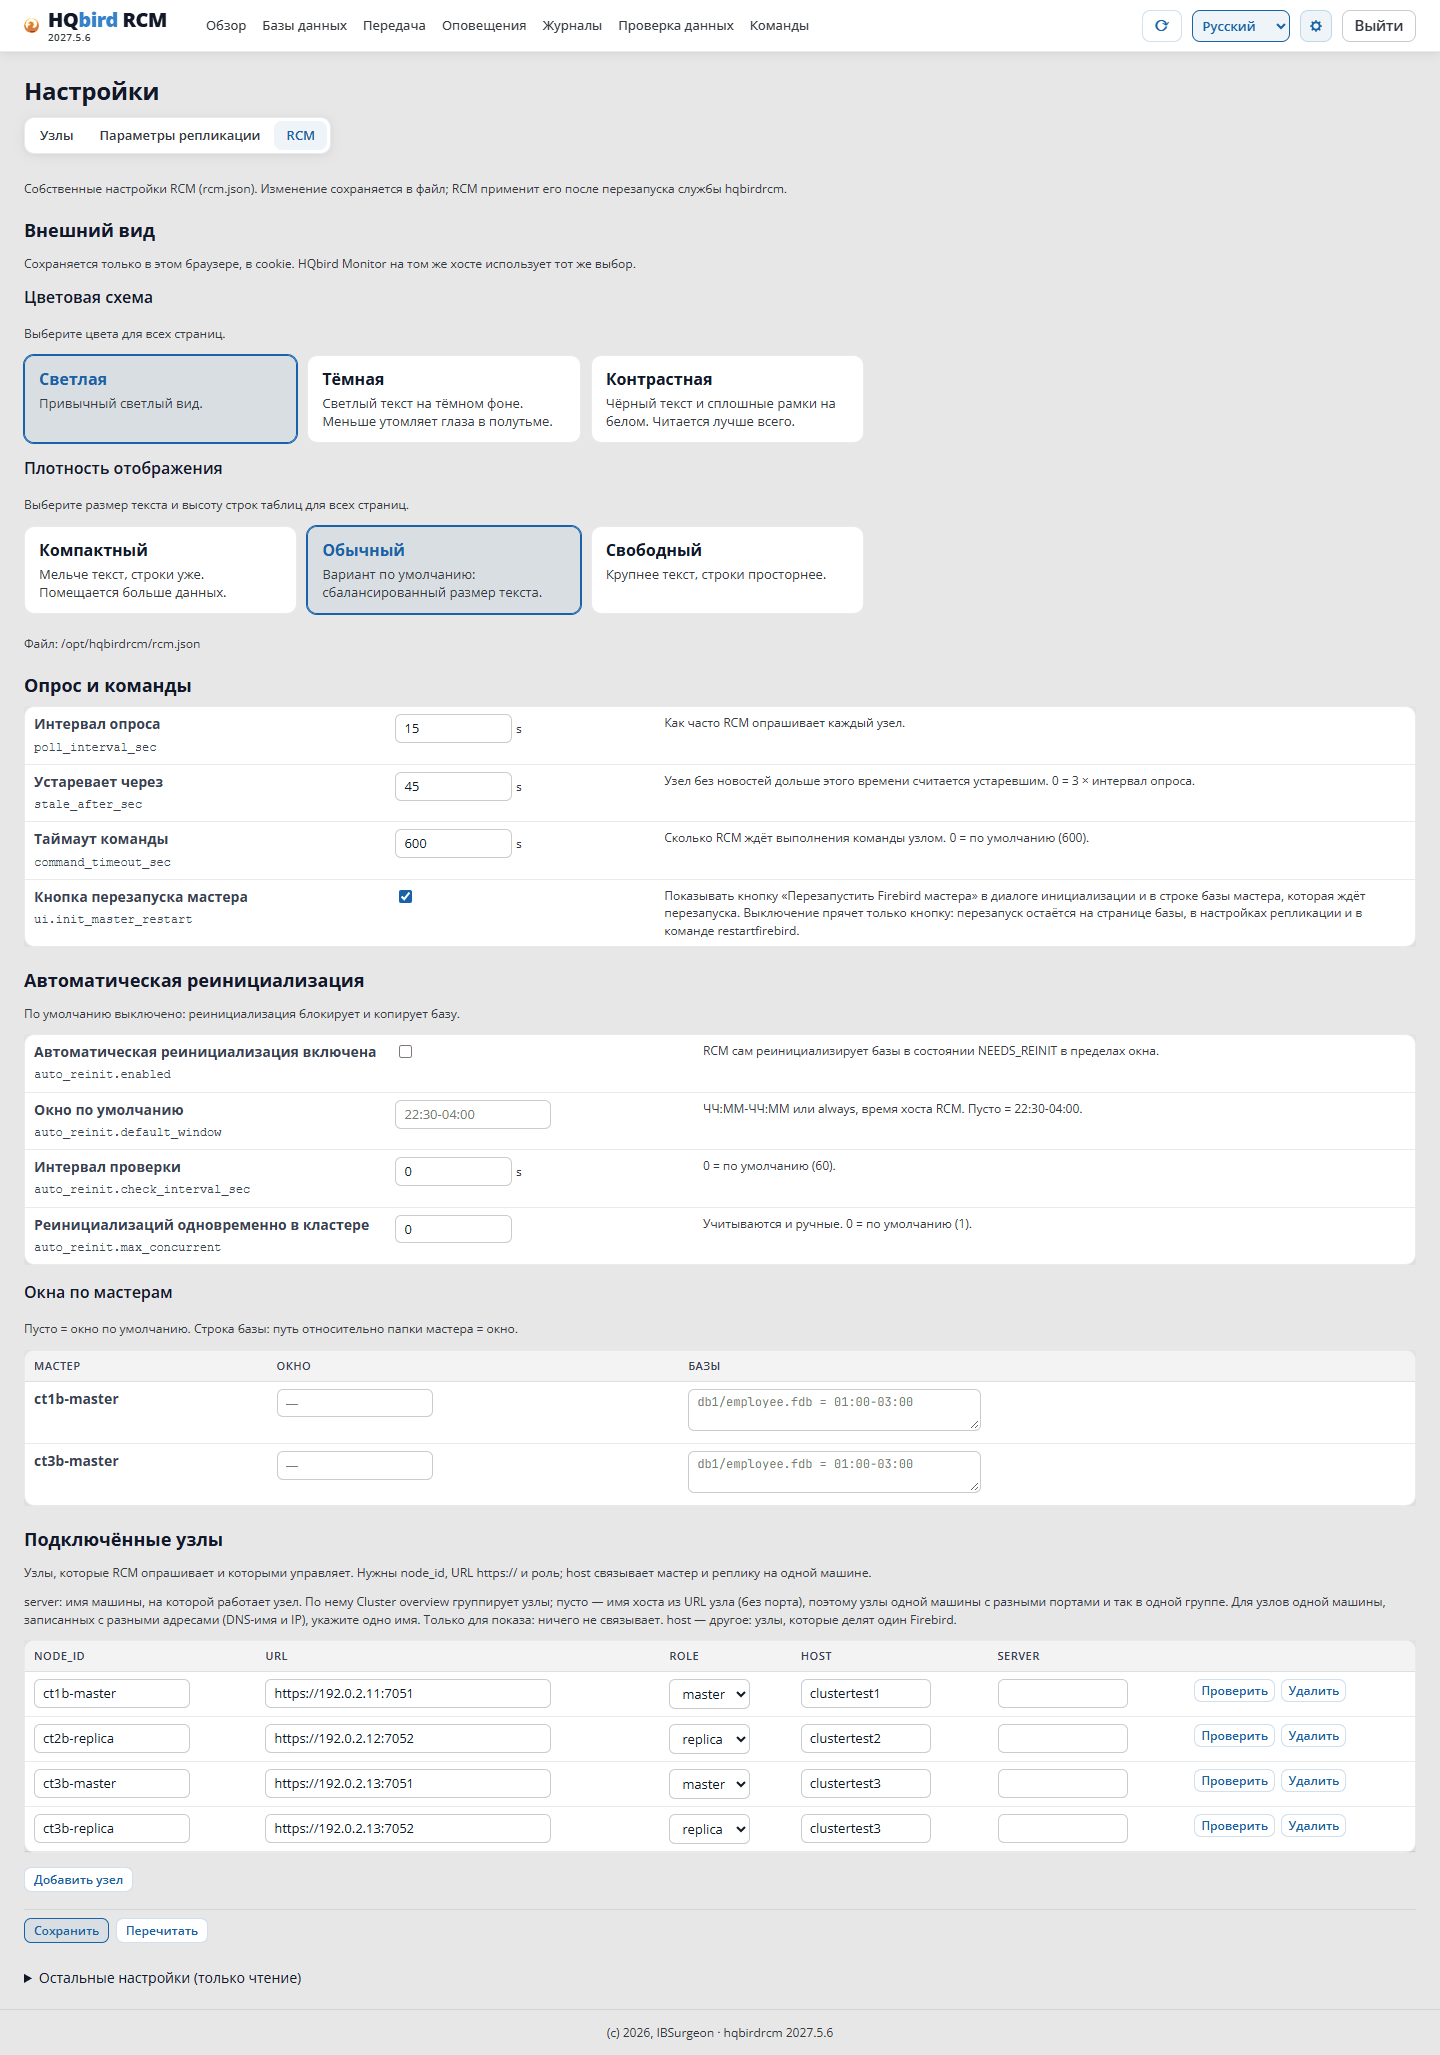
Manual installation: add a node to RCM
Settings → RCM, the Connected nodes table.
Click Add node. Fill in node_id, url
(https://<address>:7051), role, host (Firebird instance label),
server (for on-screen grouping only).
Click Validate in the node row: RCM will check the connection and permissions.
Click Save. RCM will write rcm.json and save the old file as
rcm.json.<UTC time>.bak (the last 20).
Restart RCM. Until the restart the old configuration is in effect;
the page shows which fields are waiting for a restart.
Settings → RCM
Command
sudo systemctl restart hqbirdrcm
You can also do it without the interface: edit rcm.json and restart RCM.
Manual installation: link master and replica
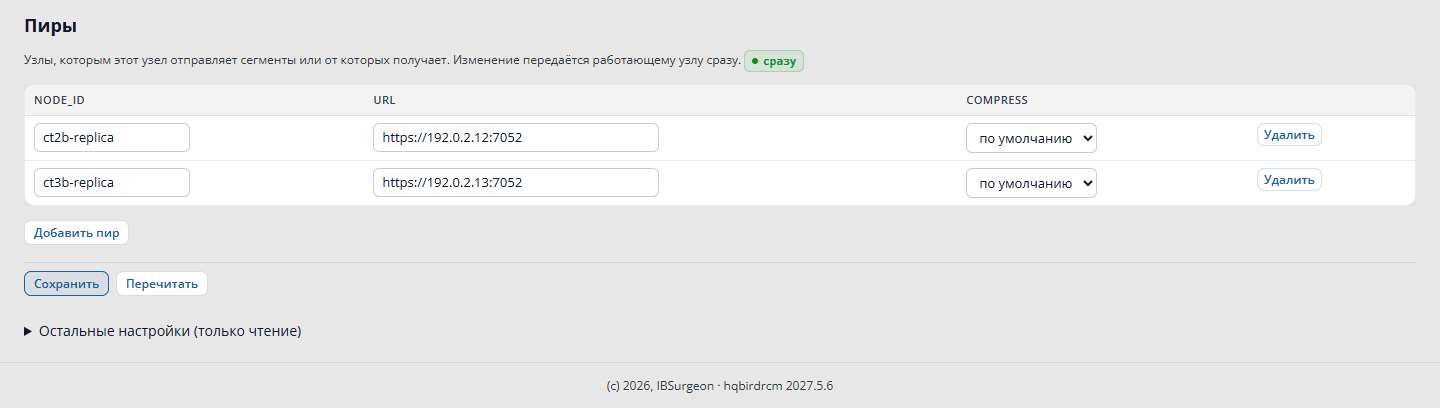
The link must be recorded on both sides:
Settings → Nodes, select the master node.
In the Peers section, click Add peer: the replica’s node_id, its url,
compression (zstd).
Click Save. RCM will show the list of changes and ask for
confirmation. The peers change takes effect immediately.
Repeat for the replica node: its peer is the master.
The master node's Peers section
If the peer is not recorded on one of the sides, RCM will not offer that replica node when
initialising the database.
2.4. Node settings
Settings → Nodes shows the node.json settings that the node allows to be changed from RCM. Only the changed fields are saved, after a window listing the changes.
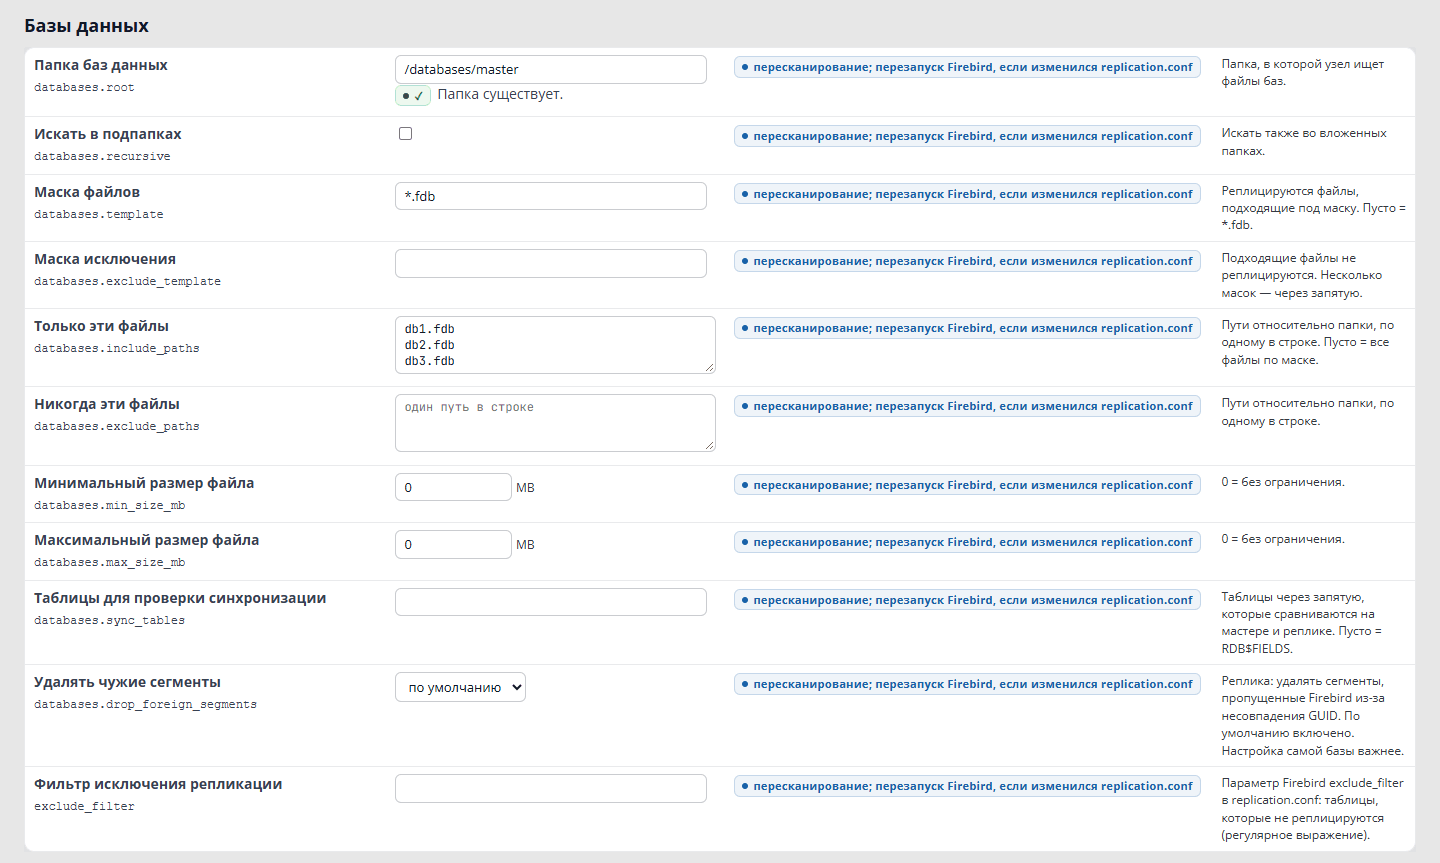
Settings → Nodes: selecting a nodeNode database settings with "after scan" markers
Each row is marked with when the change will take effect:
When
Which settings
Immediately
channel_a_mbps, channel_a_burst_mbps, windows.restart_window, peers; from HQbird 2027.2.24 — data check settings (limits.data_check_*); from HQbird 2027.2.31 — advertise_addr
After node restart
the remaining limits, windows.transfer_window; the page shows them on a separate line until the node is restarted
After scan
databases.*, exclude_filter; if replication.conf has changed, a Firebird restart is required (chapter 3.5)
Read-only (changed in node.json on the node host): firebird (including the password and auto_restart), rcm, tls, segments, the listen_addr address.
Main settings:
Setting
Default
Meaning
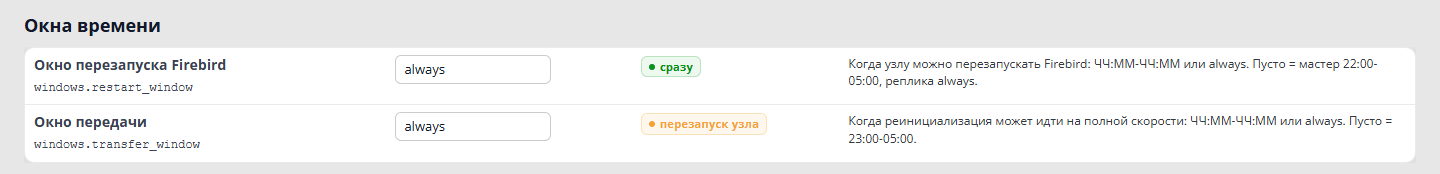
windows.restart_window
master 22:00-05:00, replica — always
when the node may restart Firebird; the Firebird master never restarts itself
windows.transfer_window
23:00-05:00
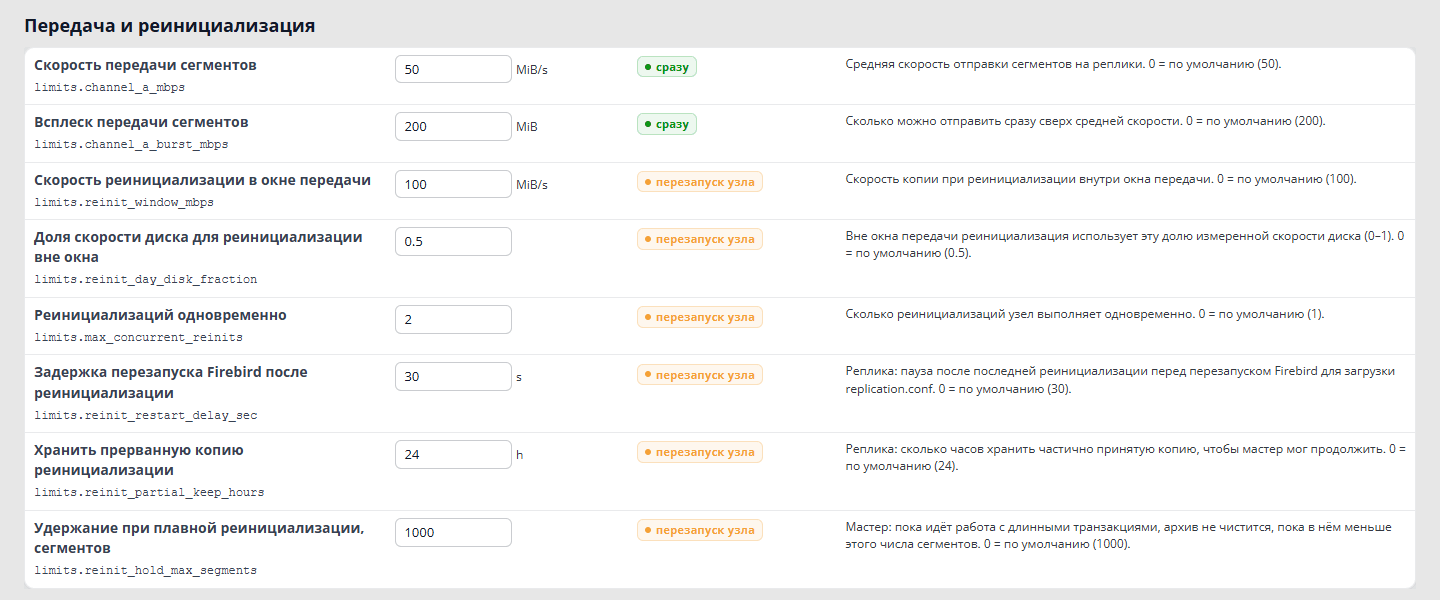
the window in which initialisation runs at the reinit_window_mbps rate
limits.channel_a_mbps
50
segment transfer rate, MB/s (channel_a_burst_mbps — short-term peak, 200)
limits.reinit_window_mbps
100
initialisation rate within the transfer window, MB/s
limits.reinit_day_disk_fraction
0.5
fraction of the measured disk speed for initialisation outside the window
limits.retention_days
2
how many days to keep sent segments in the master’s archive
limits.free_space_floor_gb
1
minimum free space, GB; below this the replica does not accept segments
limits.max_concurrent_reinits
1
how many initialisations the node runs concurrently
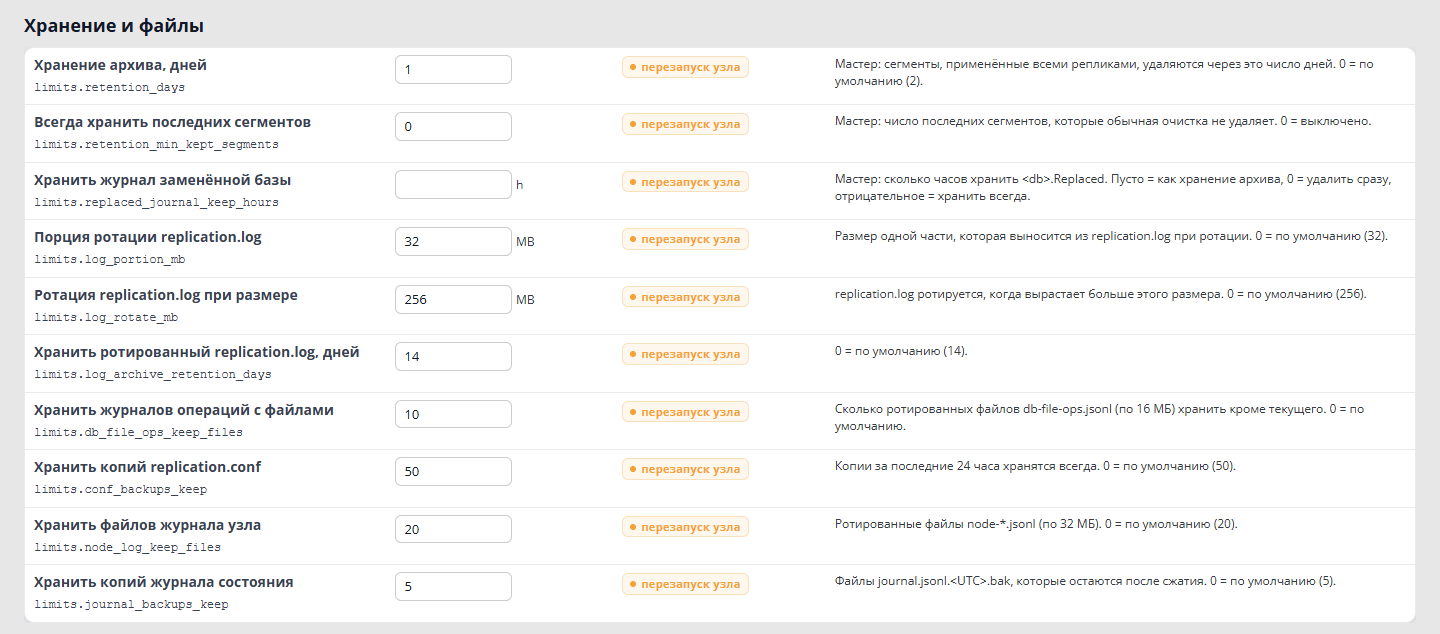
For details on speed and archive retention, see chapters 5 and 7.
firebird.auto_restart (in node.json only) determines whether a replica node may restart Firebird itself:
Value
Behaviour
auto (default)
may, if this Firebird does not serve master databases
never
never
always
always, even if this Firebird hosts master databases
Via HQCenter Admin. The fbagent node’s windows.transfer_window is also used as the window for restarting the node service itself when the cluster changes. If the window is not set in node.json, fbagent restarts the service immediately.
2.5. Multiple HQbird instances on one host
fbagent restarts the services listed in firebird.update.services of its
configuration. An empty list means all HQbird services on the host. Leave only
the service of your own instance in the list. The node does not see this setting and writes a
warning fbagent_shared to the log if fbagent knows about more than one instance.
2.6. SYSDBA Password
The node connects to Firebird with the user and password from firebird.user and
firebird.password in node.json. fbagent stores its own copy of the password. If you
have changed the SYSDBA password:
Correct firebird.password in node.json of every node of this
instance (master and replica).
Correct the password in the fbagent configuration and reload it (see the
fbagent documentation).
Restart the node services.
Otherwise the publication and verification pages in RCM will show a login error
(SQLSTATE 28000).
2.7. RCM users and audit
Users are in the rcm-data/users.json file (chapter 1.5). Without a role, a
user has all rights; the viewer role (from HQbird 2027.2.31) — view only.
A session lasts 12 hours after the last action.
After 10 failed logins within 5 minutes, login for that user and address is
temporarily blocked. A successful login resets the counter.
The audit log is the rcm-data/audit.jsonl file: one JSON line for each
change, login and logout. There is no audit log in the interface.
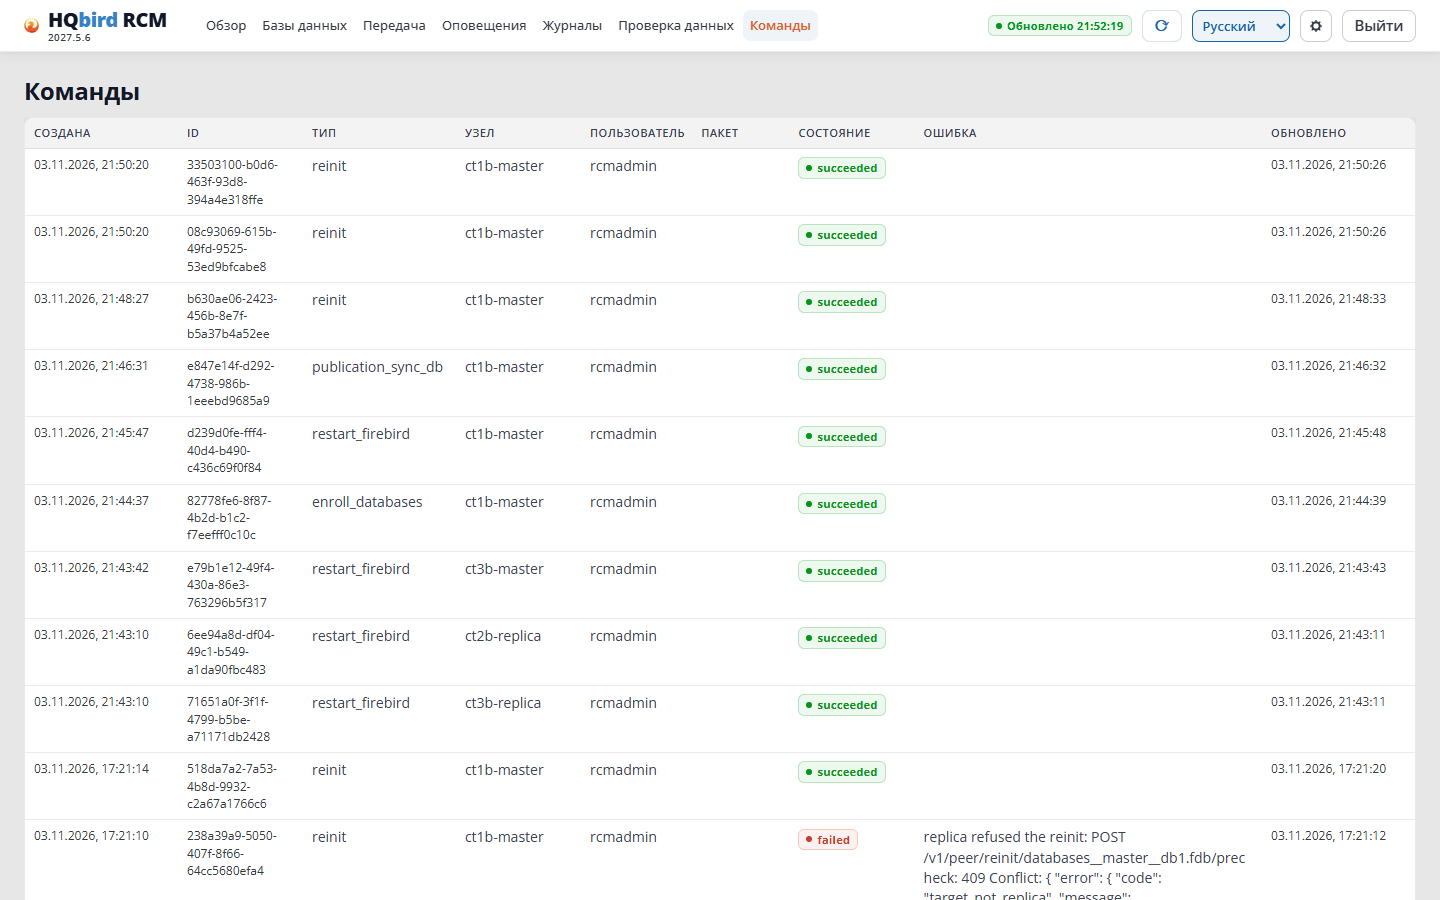
The Commands page shows the author of each command.
2.8. Licence
Once a minute, the master node reads the fbagent licence of its host. If there is no licence (the trial period has ended, the licence has expired or is invalid), the node stops shipping segments for all databases on the master. Firebird and the databases keep running, but replicas stop receiving changes.
What you see in RCM:
the master is red (NEEDS_ATTENTION), with a “no license: shipping stopped” badge;
there is no Resume button: only the licence clears the pause;
on the replica: “not receiving since …: the master has no license”;
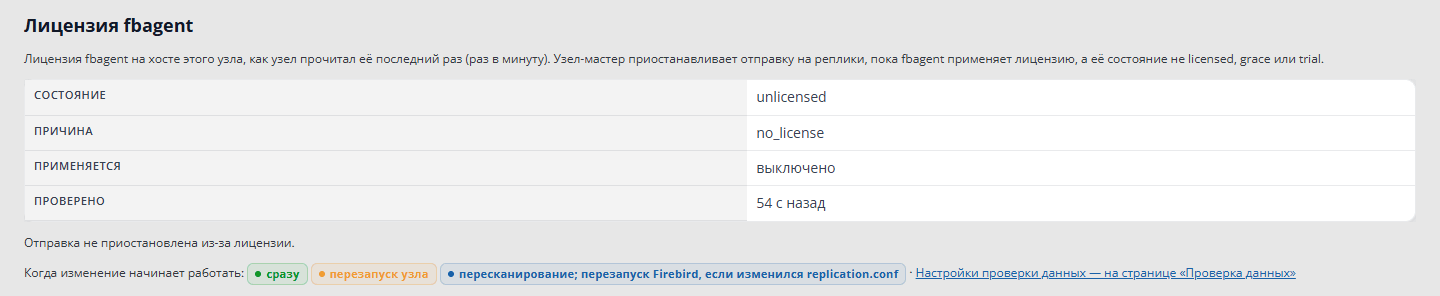
in the Nodes table, a “no license” badge; in Settings → Nodes, the fbagent licence block;
the alerts license_paused and license_pause_archive_released;
initialisation is prohibited (license_paused).
fbagent licence block in Settings → Nodes
Install the licence in fbagent. The node clears the pause on its own within a minute. The master retains the archive for replicas for limits.retention_days (2 days by default) from the start of the pause. If you install the licence later, the replicas will have to be initialised again.
Cluster via RCM, without HQCenter Admin. A floating licence without HQCenter Admin stops working after online_check_days plus the grace days. Each fbagent in the cluster needs a bound licence (fbagent --license-request, then fbagent --license-install, chapter 1.3, “Licence”). After the trial period, fbagent will not add a new node or RCM without the cluster feature in the licence; it never prohibits updates. For HQbird 2.5/3.0, the replconf_valid_till date in RCM cannot be later than the end of the licence plus the grace days on the fbagent nodes (error replconf_after_license).
2.9. How to check
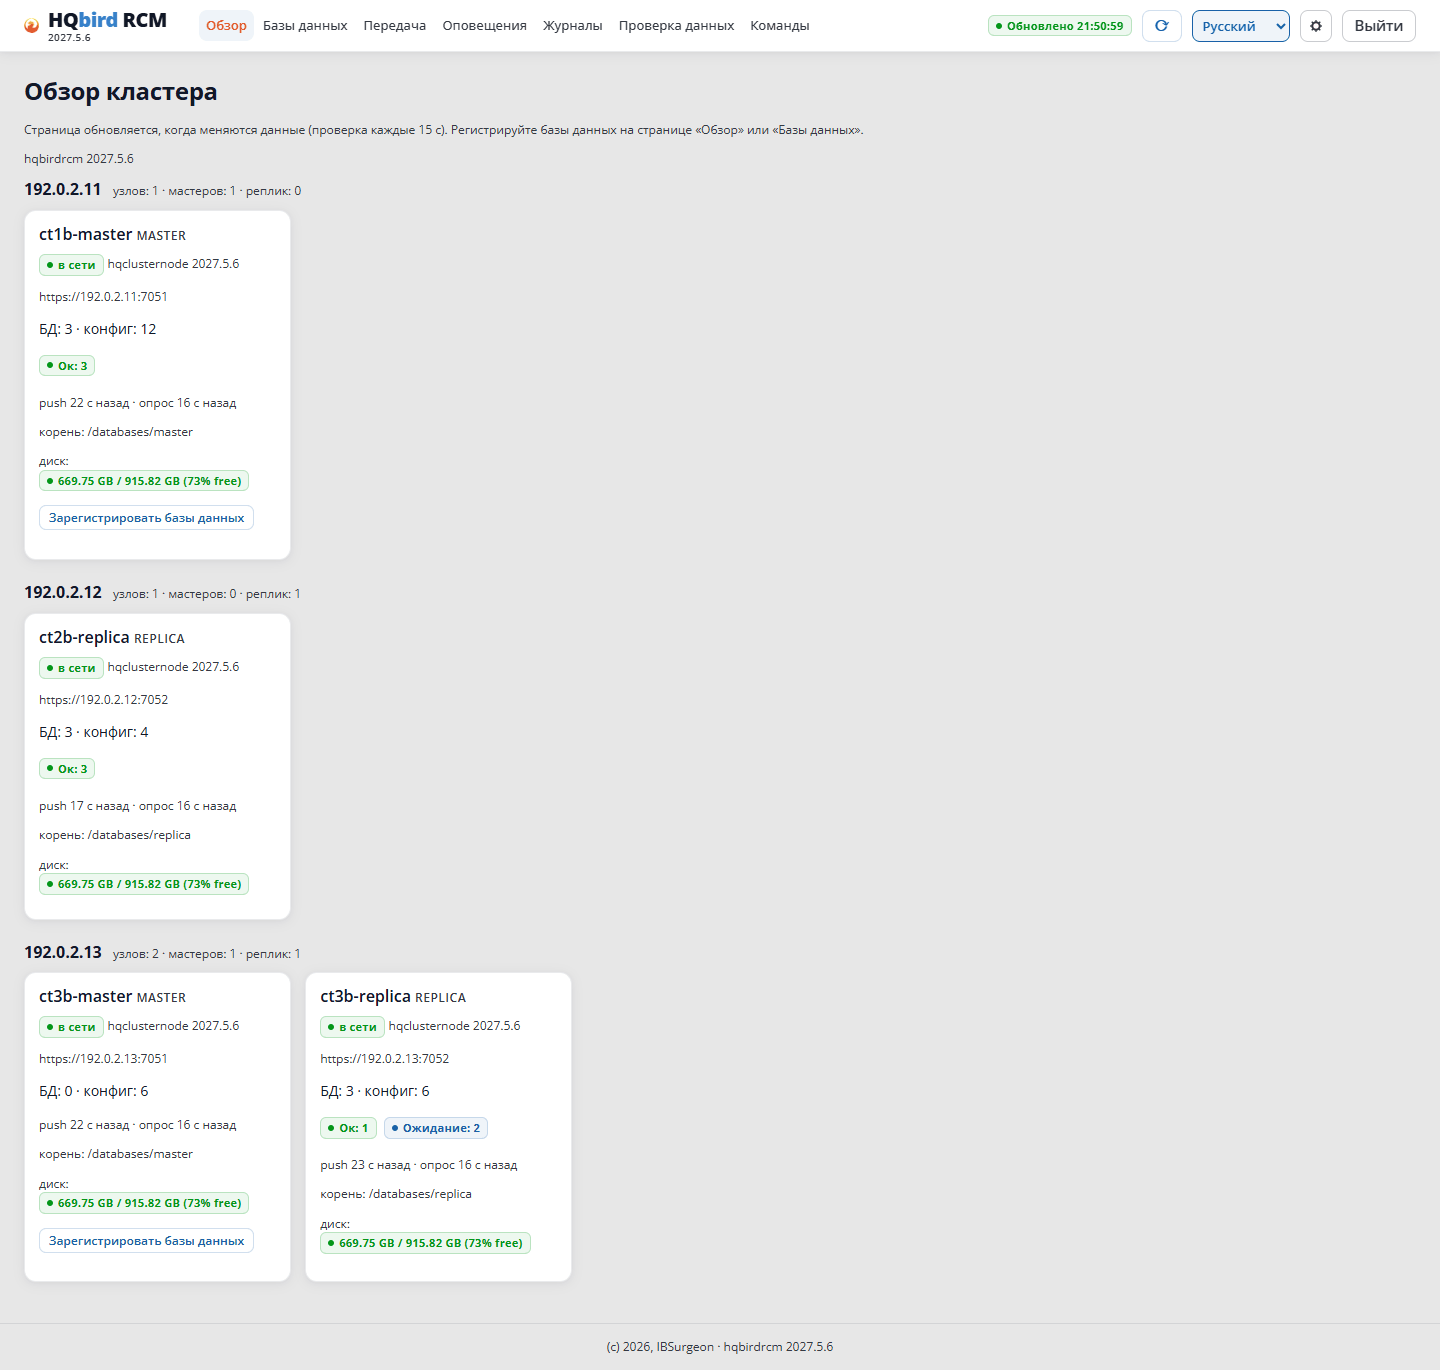
Overview: all nodes are present and grouped by server.
Cluster overview
Settings → Nodes: the master has a replica in Peers, and the replica has the master.
Settings → RCM: the Check button in each node’s row passes.
Cluster report as a single file:
Command
./hqbirdrcm report -o report.json
2.10 Common errors
What you see
Cause
What to do
Editing peers in RCM rejected (409 cluster_managed) or lost after node restart
the node was installed via HQCenter Admin or via RCM
change the links in the cluster description (2.2, 2.3)
seats_exceeded when saving the cluster in RCM
nodes on a fourth host
no more than 3 hosts with nodes
Settings → RCM: rcm_config_read_only
cluster via RCM on Linux: rcm.json is owned by fbagent
edit rcm.json as the fbagent user and restart RCM
Revoke agent does not work (agent_has_members)
fbagent has members
first delete the members and save
Replica node is not offered during initialisation
the peer is not recorded on one of the sides
add the peer on both sides (2.3)
A change in Settings → RCM does not take effect
RCM has not been restarted
restart RCM
422 when saving the cluster in HQCenter Admin
an error in the document
fix it according to the errors list, check via validate
409 when saving the cluster
the cluster was changed by someone else
re-read the cluster and retry
A new HQCenter Admin cluster member does not receive a certificate
manual approval on the RCM host
fbagent --cluster-ca-approve <id>
SQLSTATE 28000 error on publication pages
the SYSDBA password was changed
2.6
3. Adding a database to the master
In this chapter the master database comes under the control of the node. The node records it in
replication.conf and creates folders for the segments. After restarting Firebird
the database is ready for replication.
Creating the replica is the next steps (publication, initialisation). They are described in
chapters 4–6.
Button names are given according to the Russian RCM interface, with the English ones in brackets.
3.1. How a node discovers databases
The master node looks for databases in a single folder — the database root (databases.root). What comes under management is decided by rules:
Rule
Field
Default
Database folder
root
not set
Search subfolders
recursive
yes
Inclusion mask
template
*.fdb
Exclusion mask
exclude_mask
none
File size, MB
min_size_mb, max_size_mb
no limits (0)
Tables for data comparison
sync_tables
with HQbird 2027.2.24 — tables from the database publication, if none — RDB$FIELDS; in 2027.5.7 — RDB$FIELDS
Inclusion list
include_paths
empty (template mode)
Exclusion list
exclude_paths
empty
The root path is a path on the node host, not on the RCM host. The node applies the inclusion mask first, then the exclusion mask, then the size.
The rules are the same for the whole node. The sync_tables list is also shared: the check (chapter 5.10) looks for each table from the list in every database of the node that does not have its own list.
Tables for comparison, with HQbird 2027.2.24. Each database can have its own list (Synchronization tracking tables). The node stores it in databases.sync_tables_by_db. The check takes the first list that is set:
the database’s own list;
the node’s shared sync_tables list;
tables from the database publication;
RDB$FIELDS.
A shared list saved earlier takes precedence over the publication: a database without its own list uses it. The master’s database page shows which list is currently in effect (3.3).
A table that is absent from both the primary database and the replica gets the status “not in database” (absent): it is not compared, and the check will not show “Not OK” because of it. A table that is missing on only one side is a discrepancy.
RCM and node 2027.5.7. There is a single list for the whole node (sync_tables); without a list the check uses RDB$FIELDS. A missing table is an error, and the database check will show “Not OK”.
All rules are stored in the node’s node.json. The node applies them on every scan.
Template mode and list mode:
Template mode (inclusion list empty): the node takes all files matching the mask, except excluded ones. A new file in the folder will be picked up by the node automatically on the next scan.
List mode (inclusion list not empty): the node takes only the files from the list. A new file will not come under management automatically — it must be added.
Choose list mode if the folder contains database copies, test databases, or other files that do not need to be replicated.
3.2. Before you begin: check permissions
The user under which Firebird and the node run (firebird on Linux,
LocalSystem on Windows) must have read and write permissions on:
the database root folder and database files;
replication.conf and its folder (the node replaces the file via a temporary file);
the segment folders <database>.ReplLog and <database>.LogArch (the node creates them itself).
RCM checks permissions before registration (preflight). If the check fails,
the command terminates with the error preflight failed on <node> and a list of paths.
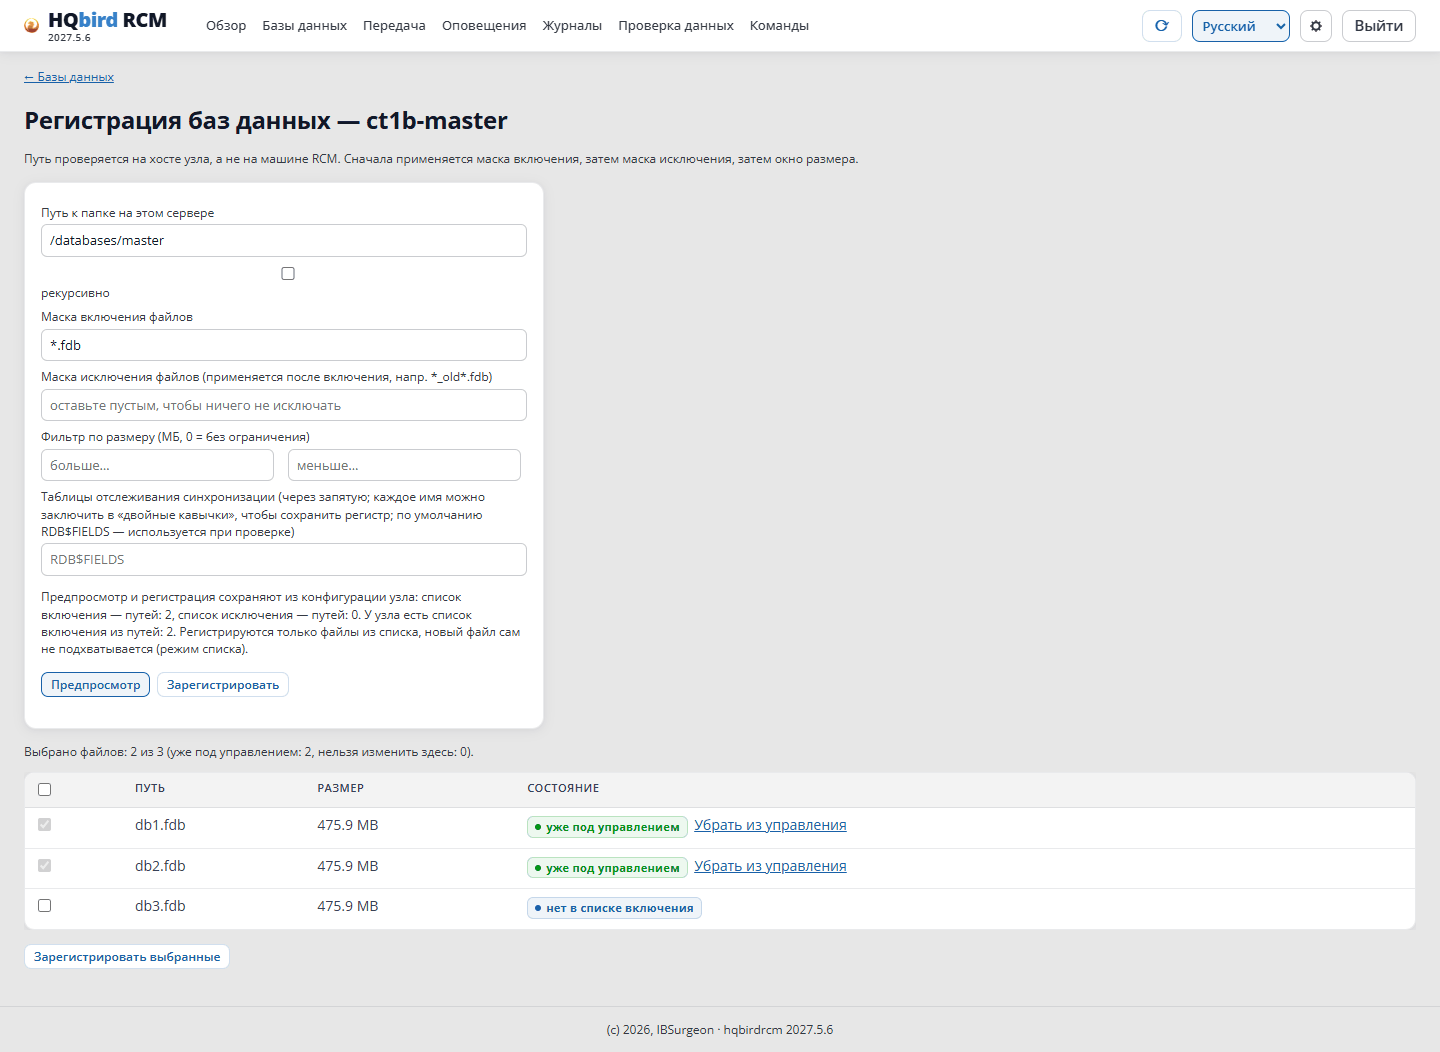
The form shows the node’s current rules (the node sent them itself). If the node
is not responding, the preview and enroll buttons are disabled: without the current
rules they would reset the include and exclude lists.
Fill in or correct the fields: Path to the folder on this server,
recursive, masks, Size filter, Synchronization tracking
tables.
The Synchronization tracking tables field:
with HQbird 2027.2.24 and later — the list is per database that this action
will enroll. Empty field: the database uses the tables of its own publication. Enrollment does not change the node’s shared
list (sync_tables). If it exists, the form says so: a database without its own list uses it
rather than the publication.
The list of an already managed database is set on its page: Databases →
master database → Synchronization tracking tables block. The block
shows which list is currently in effect. An empty field removes the database’s own
list;
in RCM and node 2027.5.7 — a single list for all databases of the node
(sync_tables).
Click Preview. The node will show all files matching the include
mask. It changes nothing.
Check the list. Each file has a checkbox:
checked — the file will be managed;
checked, locked, marked already managed — the database is already
enrolled;
locked with a reason — the file is excluded by mask, size or the exclude
list. To take it, change the rule.
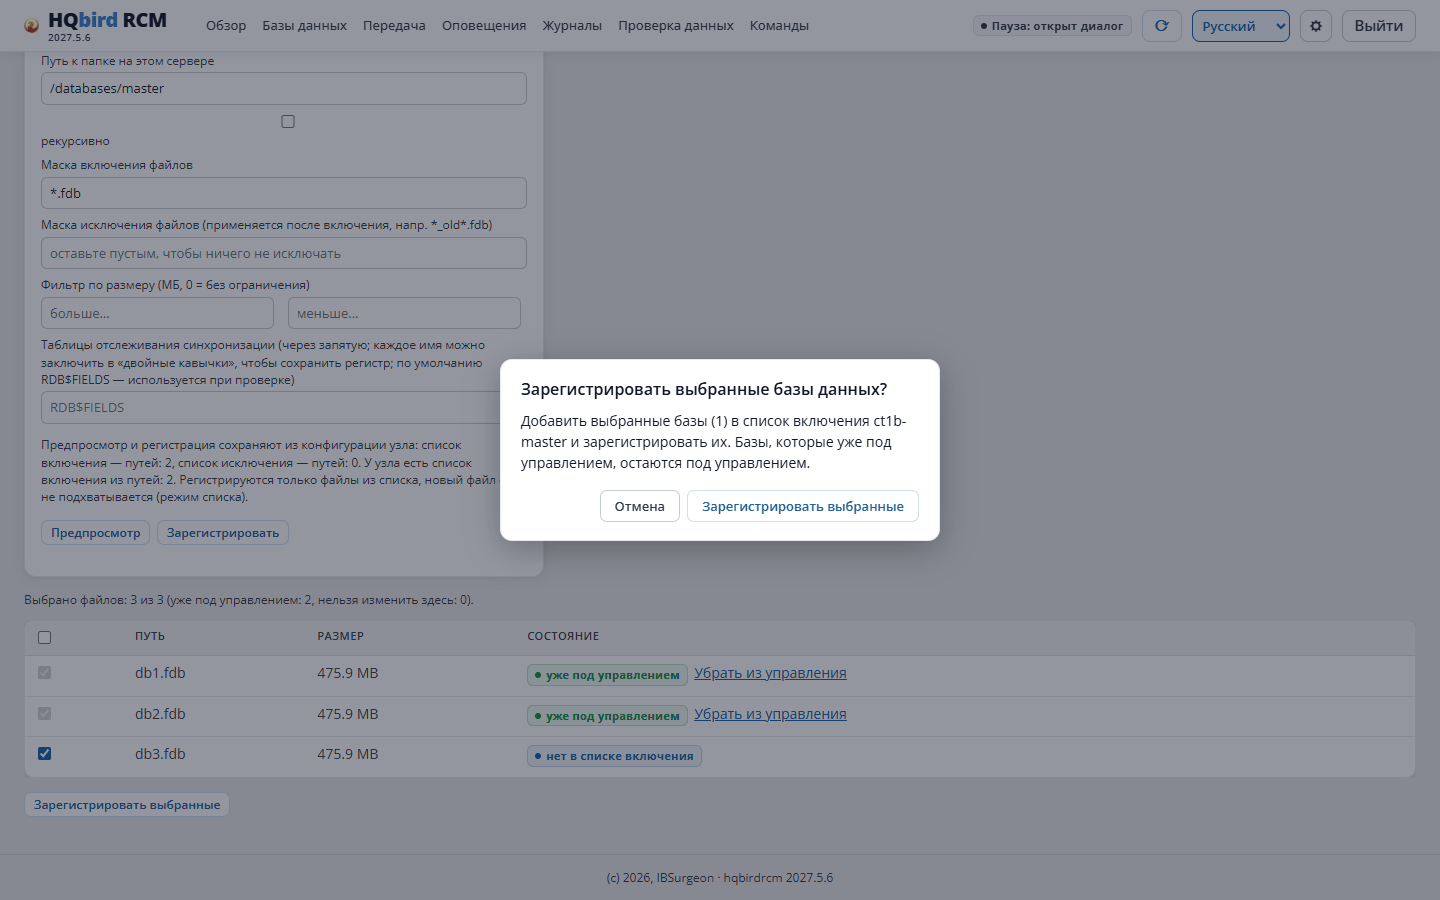
Check the required databases and click Enroll
selected. RCM will ask for confirmation and show the number of files.
Enrollment confirmation
What this button does:
in template mode — files without a checkbox are added to the exclude list, files with a
checkbox are removed from it;
in list mode — files with a checkbox are added to the include list.
The button adds databases to those already under management. It does not change
locked rows.
7. The Enroll button applies the form without changing
the lists.
8. Wait for the completion message and the number of added databases. If there is no
response for a long time, check the result on the Commands page.
With HQbird 2027.2.24 and later the message is “Enrolled: N”. If the master’s Firebird
needs to be restarted, RCM says which button to press (usually
Restart master Firebird in the database’s row) and provides a link to the master
databases.
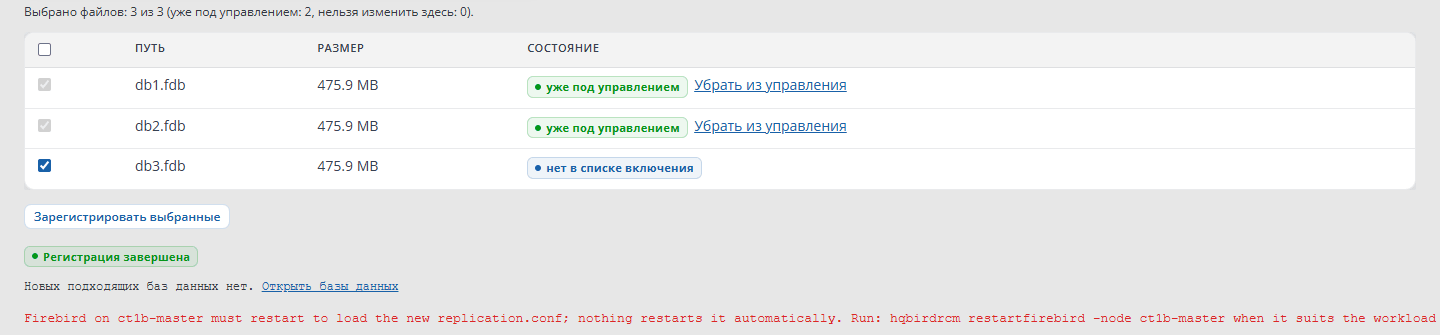
RCM 2027.5.7 may say “No new suitable databases”, even though databases
have been added: check the Databases page.
Enrollment result
If no databases were found after enrollment, but the node already had databases, the node
refuses (409) and returns the old rules. This way a mistake in the path does not disable
replication of all databases.
Note: the command sends only the fields from its parameters. The remaining
rules (masks, sizes, include and exclude lists, sync_tables) will be reset by the
node. The command has no parameters for these rules. Before
running the command, check the current rules (hqbirdrcm getconfig -node node-a). If
they are set, use the enrollment page.
3.4. What happens after registration
The node writes the rules to node.json.
The node scans the folder (scansync).
For each database found, the node writes a block into its own area of
replication.conf (between the lines # BEGIN managed-by:node-a role:master and
# END …) and creates the folders <database>.ReplLog and <database>.LogArch. The node does not modify text outside its own area.
Before making a change, the node saves a copy of the file:
replication_YYYYMMDD_hhmmss_NNN.conf.
If replication.conf has changed, the databases enter the
PENDING_RESTART state: Firebird will only read the new file after a
restart. In the Nodes table this is shown in the Pending
restart column.
The “Pending restart” column in the “Nodes” table
States of a new database:
State
Group in RCM
Meaning
UNCONFIGURED
Pending
database found, configuration not yet written
PENDING_RESTART
Pending
configuration written, Firebird restart required
CONFIGURED
Pending
Firebird restarted, database ready for publication and initialisation
3.5. Restarting the master Firebird
The master node never restarts Firebird by itself. Neither does RCM. Restarting
the master is the operator’s decision: a restart drops all connections to
all databases of that Firebird instance.
Choose a low-load time and click one of the buttons:
Restart master Firebird — on the Databases page, in the row of the
master of the database that is awaiting a restart;
the same button in the Initialize window, chapter 5;
Restart Firebird — on the database page.
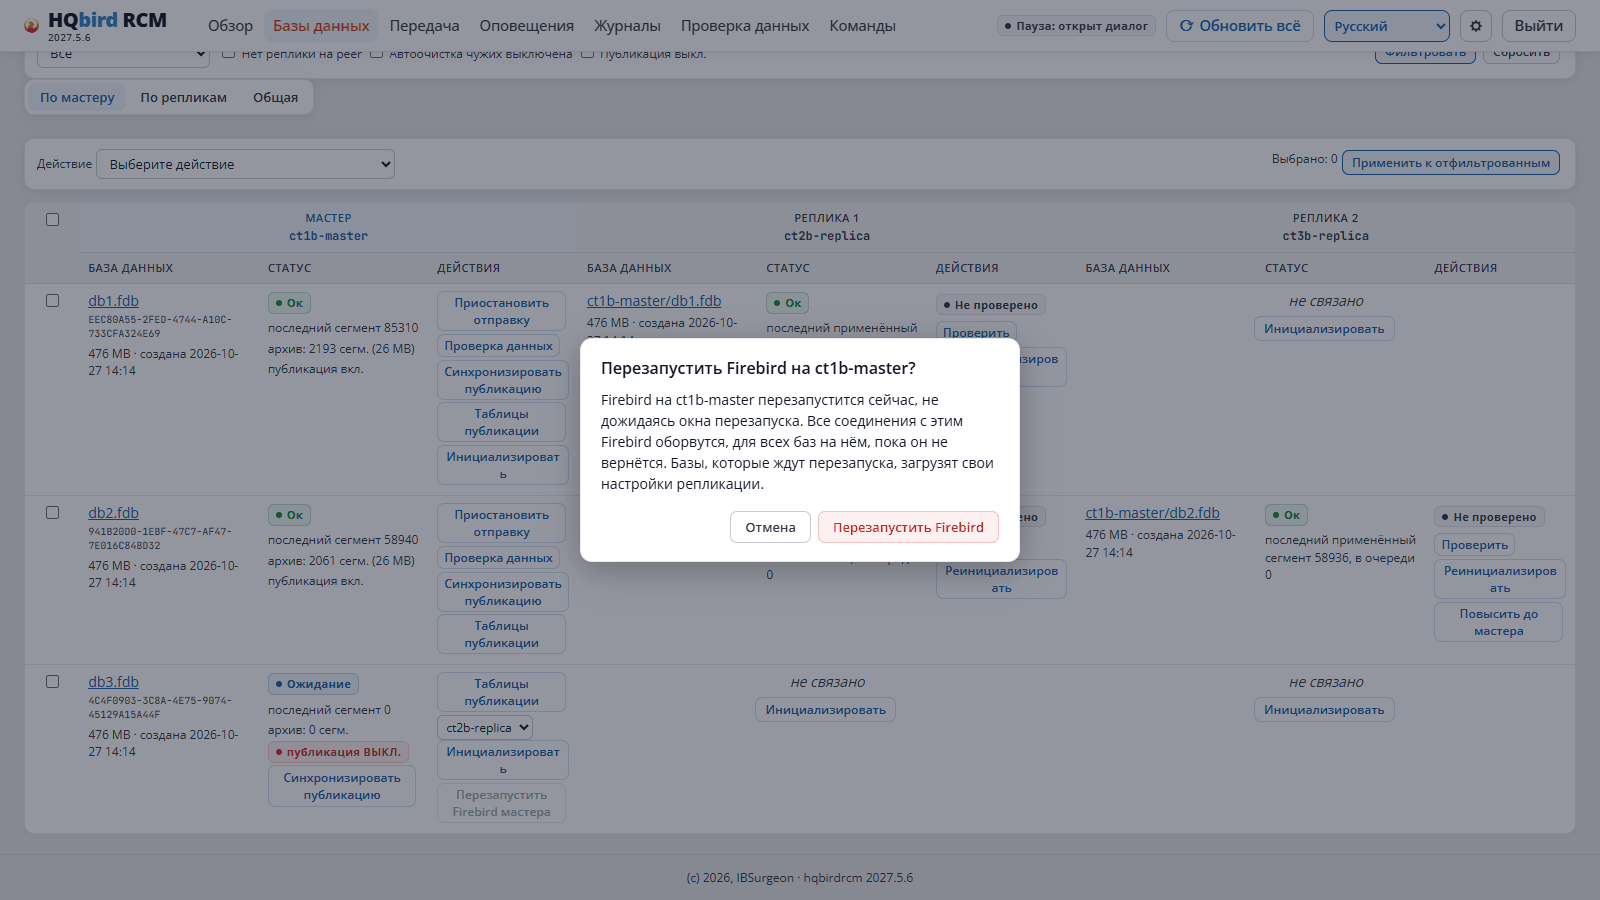
RCM will ask for confirmation. It shows the node name and a warning: Firebird
will restart immediately, without a restart window, and all connections will be dropped.
Confirmation of master Firebird restart
The same from the command line
Command
hqbirdrcm restartfirebird -node node-a
This command also restarts immediately, without a restart window.
How the node restarts Firebird:
Checks that fbagent is responding and manages the same instance
(identifier, port, service name from node.json). If any value does not
match, the node refuses.
Asks fbagent to restart Firebird.
Waits for Firebird to respond on its port.
Moves the databases from PENDING_RESTART to CONFIGURED.
Several HQbird instances on one host. fbagent restarts the services listed in
firebird.update.services of its configuration. An empty list means all
HQbird services on the host. If there are two HQbird instances on the host, leave
only your instance’s service in the list. Otherwise, restarting one node
will also stop the other instance.
On Windows. If replication.log has grown to log_portion_mb or more,
the restart proceeds as follows: stop Firebird → archive the log → start.
3.6. A database that is already replicated manually
If replication is already configured manually for a database (its own block in
replication.conf, publication enabled, segments flowing), it can be brought under
management without re-initialising the replica. For this there is a
detect_existing mode (master only).
In the response, taken_over lists the databases that will be migrated. Add -verbose
to see the skipped databases with the reason.
If the list is correct, run the command without -dry-run.
The node migrates a block only if:
the segment folders are named exactly <database>.ReplLog and <database>.LogArch;
segments already exist in the archive;
publication is enabled in the database.
The node does not migrate a block with different paths and reports it as “found but
unsupported”.
After migration the databases get PENDING_RESTART, even though the replication settings
are not changed: only the position of the block in the file changes. Restart Firebird in a
maintenance window.
3.7. How to verify
Databases: the database is visible in the master node’s row, state CONFIGURED
(after restart).
Next to the database there may be a publication OFF icon: publication is not
yet enabled. This is normal, publication is the next step (chapter 6).
New database in the master row
On the node host: the database block is present in replication.conf inside the
managed-by:node-a area, and next to the database there are the .ReplLog and .LogArch folders.
3.8. Remove a database from management
The usual way is the button. On the Databases page, tick the databases,
select the bulk action Remove from management and
click Apply to selected. RCM:
adds the files to the node’s exclusion list;
scans the folder once: the database blocks are removed from replication.conf;
deletes the database records in the node.
The database files and segment folders remain on disk. Firebird is not restarted.
Firebird continues to write the database segments until its next restart;
RCM will say if a restart is needed.
RCM will refuse (has_replicas) for a master database that has a live replica:
otherwise the replica would silently stop. First turn the replica into an ordinary database or
remove it (chapter 8).
Do not delete the database block from replication.conf manually: on the next
scan the node will write it again.
If the database file has disappeared or has been excluded by a rule. Then the database gets
the state ORPHANED (the Orphaned group). The node keeps its record and the segment
archive: a missing database is more often a mistake than a decision. If the file comes back, the database
works again and the alert is cleared. To delete such a database permanently,
perform two steps in this order:
After forgetdatabase the cleanuparchive command will no longer find the database. Both
commands work only for a database in the ORPHANED state and do not touch the database
file.
Caution. After promoting a replica to master (chapter 8), do not run
cleanuparchive -orphaned for the old record: the new master uses the same
.LogArch folder, and the command will delete its working archive.
3.9. Changing the database root
Registration with a different path is permitted. The node:
adds databases from the new folder;
moves databases from the old folder that are not present in the new one to ORPHANED (notification
orphaned_database) and keeps their archives.
If you chose the wrong folder, register the correct folder again. A database with the
same full path will continue to operate under the same db_id. A database at a different path
is a new database (new db_id); its replica must be initialised again.
3.10. Common errors
What you see
Cause
What to do
preflight failed on node-a
no permissions on the folders
fix the permissions, retry (3.2)
409 scan_would_empty_region
the new folder contains no databases, but the node had some
check the path and the mask
Preview is empty
the mask does not match or the folder is wrong
check the path, the mask, “recursive”
Buttons are disabled, “Failed to read node configuration”
the node is not responding
check the node service and the network (chapter 1)
The database stays in PENDING_RESTART for a long time
the master does not restart Firebird by itself
restart Firebird (3.5)
Restart rejected because of fbagent
fbagent is not running or its data does not match node.json
chapter 1, checking fbagent
The new file did not appear
the node is in list mode
add the file via “Register selected”
4. How to make a database a replica: steps and disk location
This chapter covers the whole journey of a database from primary to a working replica, plus the disk space calculation. The initialisation itself is described in detail in chapter 5.
4.1. The main rule
A database appears on a replica only through initialisation from the master (reinit):
the master node itself transfers a copy via nbackup.
Do not make a copy manually:
gbak creates a new database GUID and resets the segment number. The master —
replica link breaks.
A file copy of a running database is not consistent, and RCM will see two databases with the same
GUID (duplicate_guid) and will prohibit initialisation.
An already running replica configured manually can be taken under
management without a new copy — see 4.6.
4.2. Stages
No.
Stage
Where
Master database state after the stage
1
Registering the database on the master
chapter 3.3
PENDING_RESTART
2
Restarting the master’s Firebird
chapter 3.5
CONFIGURED
3
Synchronising the publication
chapter 6
CONFIGURED, publication ON
4
Preparing the replica: folder, permissions, Firebird version
4.3
—
5
Checking free space on the master and on the replica
4.4
—
6
Initialisation
chapter 5
SEEDING → IN_SYNC
7
Restarting the replica’s Firebird (if needed)
chapter 5.6
the replica starts applying segments
8
Verifying the data
chapter 5.10
—
Stage 3 is mandatory for Firebird 4/5. Without a publication, the master’s Firebird does not write
table changes to segments, and the replica silently falls behind the master. On the
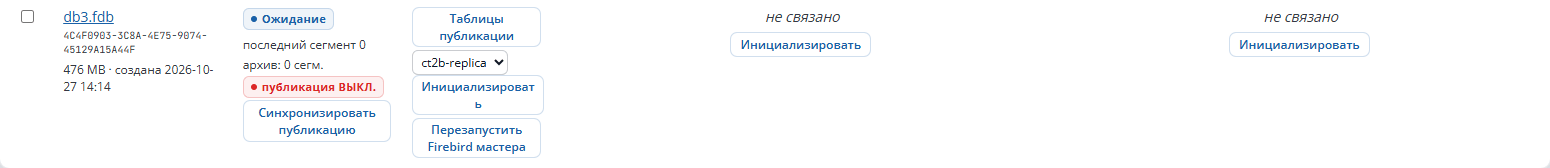
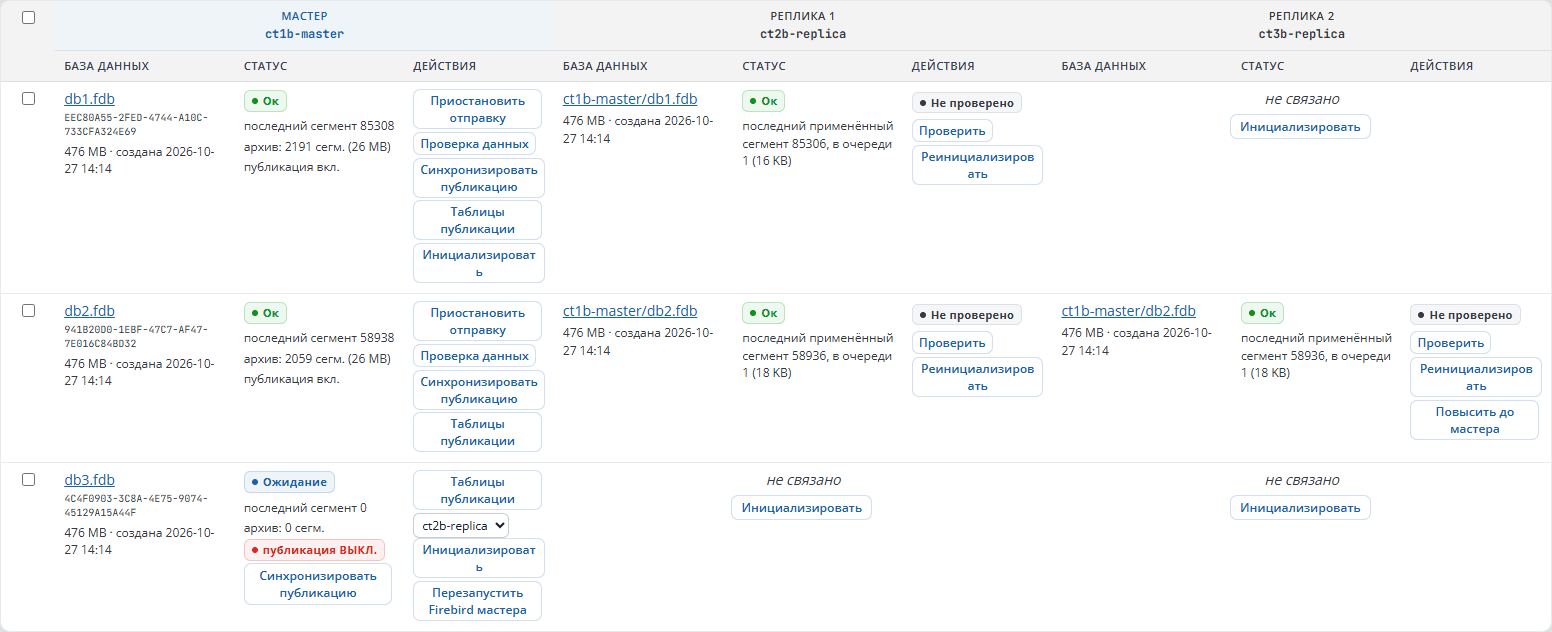
Databases page such a database is marked with the publication OFF icon. Click
Synchronise publication (Sync publication) before initialisation.
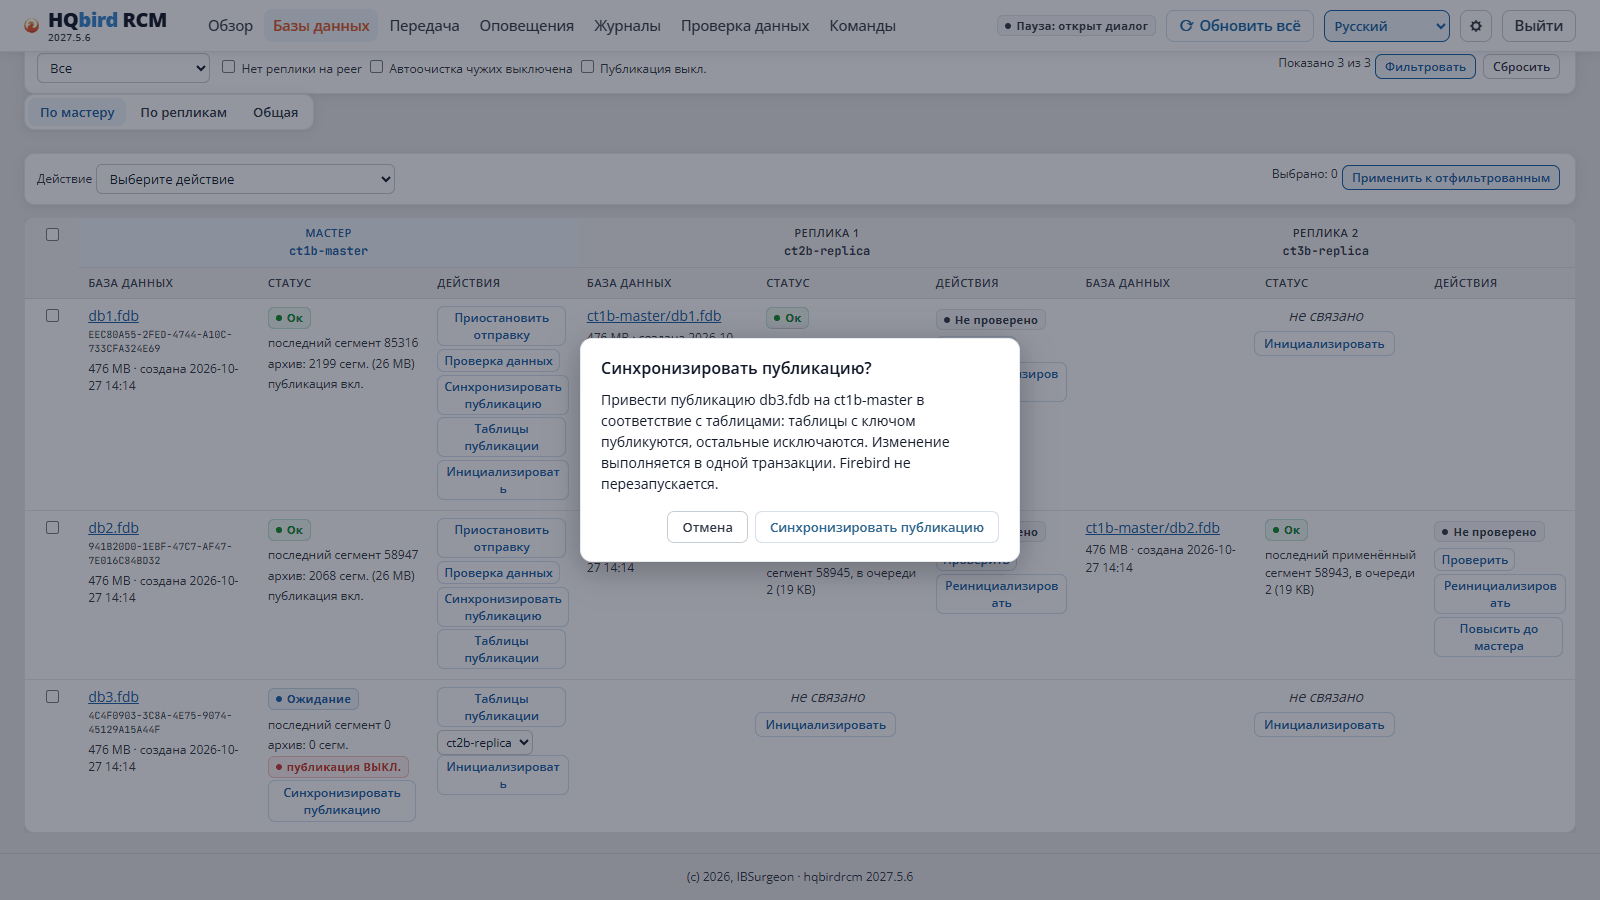
As of HQbird 2027.2.24, the Initialise window warns about this and
offers a Synchronise publication and initialise button, while the master
node refuses initialisation with the publication_off error (chapter 5.1).
RCM and node 2027.5.7 do not check the publication.
HQbird 2.5/3.0. There are no publications, so stage 3 is skipped. The set of tables is defined by
the replconf plugin filters (chapter 6).
Database states:
State
Group in RCM
Meaning
CONFIGURED
Pending
Firebird has read the settings, there is no replica yet
PUBLISHING
Pending
publication synchronisation is in progress
SEEDING
Pending
initialisation is in progress
IN_SYNC
Ok
the replica has received all segments
LAGGING
Pending
the replica is lagging, segments are queued
NEEDS_REINIT
Error
the replica must be initialised again
FAILED
Error
the last initialisation failed
4.3. Preparing the replica
Replica database folder
The replica node places each database in its own databases.root folder at the path:
Code
<databases.root>/<master node name>/<database path relative to the master root>
Example: master node-a with root /databases/master and database
/databases/master/sales/employee.fdb. On replica node-b with root
/databases/replica, the database will be here:
Code
/databases/replica/node-a/sales/employee.fdb
This way, databases with the same names from different masters do not clash.
Nobody creates the root folder automatically — neither the installer, nor HQCenter Admin, nor the node at
startup. Create it in one of the following ways:
in the Initialize window: the Replica folder field, the
Create folder button. The button is visible only when the folder does not exist. With HQbird 2027.2.24,
if the replica node does not yet have a databases.root, the field already contains
/databases/replica/<replica node id>. For a replica on Windows the field is empty:
enter a folder with a drive letter. Each replica node on the same host needs its own
folder. The folder is created by the replica
node: owner — firebird (or the node service user), permissions
2770. If the node cannot create it, the window will show the command for the replica
host. If you specify a different folder, RCM will write it to the replica node’s
databases.root before initialisation;
The setgid bit (2770) is needed so that all files inside get the Firebird group.
You can change the replica root only while it has no databases: otherwise the old databases
will end up outside the scan. To put a single database in a different location, use
Move on the database page.
Permissions
The replica node and Firebird must be able to write to the database root. The node checks that
the placed files will get the folder’s group. If it cannot — it refuses with
ownership_unfixable and text on how to fix it (usually the node service runs with
Group=root).
With HQbird 2027.2.24, the Initialize window also shows a folder that
exists but that the node service cannot write to: the node’s text with the fix
command and a Check again button. RCM 2027.5.7 in this case says
“Folder exists”: check the permissions yourself (hqbirdrcm checkpermissions -node <replica> -root <folder>).
Firebird version
The major Firebird version on the replica must match the master (5.0 → 5.0,
4.0 → 4.0). Otherwise the replica will refuse before any data transfer:
incompatible_engine.
Connectivity
The replica node must be a peer of the master, and the master must be a peer of the replica (chapter 2).
Otherwise RCM will not offer this node in the Initialize window.
4.4. How much space is needed
In brief
Where
What
How much
Master, database volume
free before initialisation
≥ 105 % of the database size
Replica, database folder volume
free before initialisation
≥ 105 % of the database size, with HQbird 2027.2.24 — plus free_space_floor_gb (plus the old file, if the replica already existed; with the Remove the old replica checkbox — without it)
Master, <database>.ReplLog
Firebird working segments
up to 64 segments × segment size (16 MB by default) ≈ 1 GB per database
Master, <database>.LogArch
archive of segments for replicas
changes over retention_days (default 2 days) + whatever the replicas have not yet confirmed
Replica, <database>.Incoming
queue of segments to apply
up to 256 segments × 16 MB ≈ 4 GB per database in the worst case
Replica, whole volume
headroom
at least free_space_floor_gb (default 1 GB)
Checking space before initialisation
Initialisation checks space twice and only before locking the database:
RCM — from the latest node statistics, before sending the command. If space
is clearly insufficient, RCM immediately returns error 507.
Master node — a live measurement on its own volume, then a request to the replica so that
it measures its own. If there is not enough on at least one side, initialisation
ends at the SPACE CHECK step with the error
insufficient disk space on master or … on replica.
The requirement on both sides is 105 % of the master database size.
With HQbird 2027.2.24 the replica node calculates as follows:
it needs 105 % of the database size plus the replica’s free_space_floor_gb (7.3):
after initialisation a reserve for segments remains on the volume;
leftovers from previous initialisations (<database>.hqcluster-part, <database>.new)
count as free space: the node deletes them before the new copy;
the error text names all the numbers. It also names the files
<database>.pre-reinit-*.fdb and <database>.failed-seed-*.fdb with their size. The node
never deletes them: delete them yourself if they are not needed.
force (forced) skips only the check in RCM. The node check
cannot be bypassed: it protects the node from running out of disk in the middle of copying.
If space is insufficient only because of the old replica copy, RCM 2027.2.24 in
error 507 names the Remove the old replica checkbox rather than force. For
this, both nodes must be HQbird 2027.2.24 or newer. Otherwise the error names
the node that needs updating, and force.
Why so much
Master. During copying the database is locked by nbackup -L. All
changes are written to the <database>.delta file next to the database. The size of .delta depends
on the write load during copying. Under heavy load and slow
transfer it can grow considerably — watch the space during the first
initialisation.
Replica. The copy is written straight to the <database>.hqcluster-part file next to
the database location. The node reserves the full size in advance. The file is then checked,
repaired (nbackup -FIXUP -SEQUENCE) and renamed into place. A second
copy is not needed — the database size is needed once, on the database volume.
If the replica already existed (repeated initialisation), the old file sits on
disk until the last step. This means the old file and the new copy are needed on the volume
at the same time. Free space is calculated without the old file — therefore the requirement
is the same: 105 % of the database size free.
Remove the old replica (with HQbird 2027.2.24). If there is no space on the replica volume
for the new copy next to the old one, tick this checkbox in the initialisation
window (chapter 5.1). The replica node then deletes the old copy and its
incoming segments (.Incoming) before transfer, and the volume has enough for 105 % of the
database size plus free_space_floor_gb. The node deletes the copy only if all conditions
are true:
without deletion there is not enough space, and with deletion there is enough;
it is a copy installed by this node’s initialisation: the header
is readable, the mode is read-only replica;
the database has not been made a normal one (no <database>.hqcluster-normal.json file, chapter 8);
overwrite_non_replica is not set (5.9).
Otherwise the node deletes nothing and refuses with the reason in the text. To delete,
the node stops the replica’s Firebird for the duration of the deletion (5.6).
The checkbox is off by default. Risk: while the transfer is in progress, there is no
database copy on the replica. If the database has only one replica, the master is unprotected
the whole time. While there is no new copy, the database on the replica is in the NEEDS_REINIT state (not FAILED and
not ORPHANED), and the replica issues the alert replica_removed_for_reinit
(warn). Once the new copy is in place, the alert is cleared. If initialisation
fails after the deletion, the pair remains NEEDS_REINIT: start the
initialisation again (or automatic reinitialisation will start it, 5.8).
A new initialisation transfers the database from the beginning.
Master archive (.LogArch). The node keeps sent segments for
retention_days days so that the replica can request them again. Segments
that the replica has not yet applied are kept longer. If space is low, the node
cleans the archive in stages:
segments applied by all replicas older than retention_days;
applied segments that are newer (when space is short);
unapplied segments — only as a last resort. Then the replica
loses the segments it needs and gets NEEDS_REINIT.
If a replica is unavailable for a long time, the archive grows. Its volume = the database changes over the
downtime period.
Calculation example
Database 100 GB. Load — 5 GB of segments per day. Initialisation runs
at night, copying takes 2 hours, during which about
2 GB ends up in .delta.
Replica, repeated initialisation with the Remove the old replica checkbox (with HQbird 2027.2.24)
old file deleted before transfer: 105 GB + .Incoming up to 4 GB + 1 GB reserve
volume ≥ 110 GB
Add a reserve for database growth and for replica downtime (the master archive grows by
5 GB per day of downtime).
Segments on a separate volume
The .ReplLog, .LogArch and .Incoming folders are by default located next to the database.
They can be moved to another volume: the segments.storage parameter in node.json
(with mirror_hierarchy: true the node replicates the structure of the database folders). Then
the archive does not take space away from the databases. The 105 % check still applies to the database volume.
Where to look at space
Databases → Nodes and Overview: the free space icon for the
databases.root volume. Yellow — less than 20 %, red — less than 10 %.
Databases page: the Disk column in the Nodes table
Cluster report: hqbirdrcm report.
4.5. Multiple replicas of one database
The second and subsequent replicas are created in the same way: Initialise in the master row, selecting a free replica node.
While a new replica is being initialised, the master does not transmit this database to the already running replicas either. They will catch up with the master after initialisation finishes. The confirmation window says so.
One database — one initialisation at a time, even for different replicas.
Space on the master is checked separately for each initialisation.
Master database with two replicas
4.6. Manually configured replica
If a replica is already running from a hand-written replication.conf, you can take it under management and not copy the database again:
Master: register the databases with detect_existing (chapter 3.6).
Replica:Databases → replica node → Take over, or hqbirdrcm takeover-replica. RCM will find the replica blocks, match the files to the master databases by GUID and show for each one: in_sync, resumable or needs_reinit.
Confirm the rows. The node will move the blocks into its own replication.conf area.
Restart the replica’s Firebird so that it reads the moved blocks.
Initialise only the needs_reinit rows: the master archive no longer contains the segments required by these replicas.
4.7. Common errors
What you see
Cause
What to do
insufficient disk space on master / on replica
not enough space (4.4). On re-initialisation the old copy takes up space until the end (4.4)
free up space, retry. The second way out on the replica (from HQbird 2027.2.24) is the Remove the old replica checkbox (4.4, 5.1)
507 from RCM immediately
according to the space statistics there is clearly not enough
same. If there is space without the old copy, RCM 2027.2.24 names the checkbox Remove the old replica
incompatible_engine
different major Firebird versions
upgrade the replica’s Firebird
Folder missing on the replica node
root not created
Create folder in the initialisation window (4.3)
Folder exists, but the node service cannot write to it (from HQbird 2027.2.24)
no write permissions
run the command from the window, click Check again (4.3)
publication_off (from HQbird 2027.2.24)
the master’s publication is disabled or has no tables
Synchronise publication and initialise (5.1)
ownership_unfixable
the node service has a foreign group
fix the service group as described in the error text
duplicate_guid
two databases with the same GUID (a file copy)
remove the copy or give it a new GUID (nbackup -F)
Replica node not in the Initialise list
no connection in the peers
chapter 2
Replica IN_SYNC, but the data diverges
the publication was disabled
synchronise the publication, then repeat the initialisation
5. Initialization (reinit)
Initialization is the transfer of a copy of the master database to the replica. The first transfer
is called initialization (the Initialize button), a repeat transfer is
reinitialization (the Reinitialize button). The mechanism is the same.
Before starting, complete steps 1–5 from chapter 4:
the database is registered, the master’s Firebird has been restarted, publication is enabled,
the replica folder exists, and there is enough space. How much space is needed on the master and on the
replica is described in chapter 4.4.
5.1. How to start
Publication first. Registering a database does not include publication. Without
publication, the replica receives no changes. Before initialisation, run
Synchronise publication (chapter 6) or
hqbirdrcm setpublication -node <master>.
With HQbird 2027.2.24, the initialisation window checks the publication. If
it is off or has no tables with a key, the window shows a
warning and a Synchronise publication and
initialise button. RCM synchronises the publication, waits for the command to finish and
starts initialisation with the selection from the window.
A 2027.2.24 master node itself refuses such initialisation (and the first
one too) with the error publication_off and issues the notification
master_publication_off (chapter 6.1). After the refusal, the database cell again
has the Synchronise publication and initialise button.
If the operator turned the publication off (6.4) or removed all tables with a
key from it (6.3), synchronisation preserves that. RCM does not start
initialisation and provides a link to the Publication tables page.
RCM and node 2027.5.7 do not check the publication: initialisation
succeeds, the database shows “OK” in RCM, but the replica receives no changes. If
the publication was turned on after initialisation — reinitialise the database.
The "Reinitialise database?" window
Open Databases.
In the master database row, in the replica node column, click Initialise
(Initialize). The replica node is set by the column: it is not selected in the window. For an
existing pair — Reinit in the expanded master card.
In the window (with HQbird 2027.2.24 the title for a new pair is “Initialise
database?”; in RCM 2027.5.7 — “Reinitialise database?” and also on
first initialisation):
check the Replica folder. The window shows whether the folder exists. If it
does not, click Create folder: the replica node will create it (4.3). If the node
cannot create it, the window shows the command for the replica host. With HQbird
2027.2.24 the window also shows a folder that the node service cannot
write to: the fix command and a Check again button;
select the Reinit method: Smooth (recommended) or Standard
(5.4). With HQbird 2027.2.24, if the master’s archive has no segments yet
(usually before the first initialisation), the window shows a hint: on a
busy database Standard is faster;
if the master database is still waiting for a Firebird restart, the window will say so and
show a Restart master Firebird button. Without the restart the database
is not replicated;
Remove the old replica (with HQbird 2027.2.24, off by default)
is needed only for reinitialisation when the replica volume has no
space for a new copy next to the old one (4.4). The window shows the
numbers in advance: how much is needed, how much is free, how much the old copy occupies.
If there is space without the old copy, the window asks you to tick the checkbox. The checkbox
is inactive if the master or replica node is an old version: the window states
which node to update. Until the new copy is ready, the replica has no copy of
this database (4.4).
Confirm. RCM will state that the database will be locked on the master and
copied to the replica.
The progress of initialisation is visible in the expanded master card on the Databases
page: steps and percentages. With HQbird 2027.2.24 the progress is also visible after refreshing
the page: on first initialisation — in the replica node cell, and also in the
Reinitialisation progress row on the master database page. The
Initialise button is inactive while the master node is copying the database. If RCM is not
tracking this initialisation (for example, it was started from the node’s command line),
the steps are taken from the node state, without percentages. In RCM 2027.5.7, after
refreshing the page the progress of the first initialisation is not visible: wait until the master
database leaves SEEDING.
Initialisation steps in the master row
Every RCM command (initialisation, Firebird restart, publication
synchronisation) is recorded on the Commands page with its result.
The "Commands" page
The same from the command line
Command
# one databasehqbirdrcm reinit -node node-a -db <db_id> -to node-b
# all master databaseshqbirdrcm reinit -node node-a -all -to node-b
Parameters: -mode smooth|standard (default smooth), -hold=false
(do not hold the archive during long transactions), -allow-restart (5.6),
-force (5.9).
-remove-old-replica (with HQbird 2027.2.24) — the same as the Delete
old replica checkbox. For a single database only: -db and -to are required; with
-all the command refuses. If the master or replica node is an old version, RCM
refuses with node_too_old and sends nothing.
-all tries all databases and collects errors rather than stopping at the first one.
5.2. Steps
No.
Step (in RCM)
What happens
1
SPACE CHECK
checks space on the master and on the replica (chapter 4.4); the replica checks in advance that it can accept the file
2
LOCKING
nbackup -L: the master’s database file is frozen, changes go to <database>.delta
3
COPYING TO NODE
the file is transferred in parts: read → checksum → compression → send
4
UNLOCKING
nbackup -N immediately after the transfer: changes from .delta are returned to the database
5
SEEDING
on the replica: verification of the file checksum, nbackup -FIXUP -SEQUENCE, installation of the file, gfix -replica, writing the block to replication.conf
6
RESTARTING REPLICA
restart of the replica’s Firebird, if it is needed (5.6)
After step 6 the database gets the IN_SYNC state. The master continues sending
segments from the point where the copy ends.
What is important to know:
The master runs all the time. Users write to the database, changes go to
.delta. The lock is released immediately after the transfer.
Transactions that coincided with the lock are not lost. The node finds
the transactions open at the moment of nbackup -L, and the replica replays them from
the segments.
The transfer continues after an interruption. If the connection or the replica node
restarted, the master will continue from the last received part. An unfinished
transfer is kept on the replica for 24 hours (reinit_partial_keep_hours).
On an error the node releases the lock, deletes the unfinished file on
the replica and sets the database to FAILED. The next attempt starts from a known
state.
With the “Delete old replica” checkbox (since HQbird 2027.2.24) the replica
deletes the old copy after the LOCKING step, before the transfer. The COPYING TO
NODE step at this time shows “removing the old replica copy to make
space”. An error after the deletion gives the pair NEEDS_REINIT rather than FAILED
(chapter 4.4).
nbackup only. gbak is not used: it changes the database GUID.
5.3. Impact on operation
What
Impact
Users of the master
keep working; during copying .delta grows, after -N the changes are transferred into the database
Other replicas of this database
do not receive segments of this database while initialisation is in progress; they catch up afterwards
Other databases of the master
not affected
Firebird of the replica, new database
not stopped; restart per 5.6
Firebird of the replica, repeated initialisation
is stopped while the file is being replaced: all databases of this Firebird are unavailable for seconds
Firebird of the replica, the node deletes the old copy (“Delete old replica” checkbox, since HQbird 2027.2.24)
is stopped earlier, while the deletion is in progress, before the transfer. The node installs the new copy without a second stop if the database block in replication.conf has not changed. If there is enough space and no deletion is needed, the node deletes nothing, and everything proceeds as with a normal repeated initialisation
Network and disk
load according to the speed limits (5.5)
On Windows. A file opened by Firebird cannot be replaced. During repeated
initialisation the node stops the replica’s Firebird via fbagent, installs the
file and starts Firebird again. On Linux Firebird is also stopped before
replacement: otherwise it would continue working with the old deleted file.
5.4. Smooth and standard methods
Smooth (default). Before locking, the node looks for long transactions: user write transactions that started before the oldest segment in the master’s archive. After initialisation the replica will not be able to replay them and will stop at their first change (“Transaction … is not found”). Transactions without changes are not counted.
If such transactions exist, initialisation does not start: RCM displays Smooth reinit is waiting for long transactions and provides an Open list link.
Long transactions page: no long transactions
On the Long transactions page:
summary: how many transactions and connections, the oldest segment;
Top 5 connections with the oldest transactions: user, client, start, age, changes, current query;
Hold segments / Release hold — while the hold is enabled, the master’s archive is not purged and history is not truncated;
Disconnect selected and retry reinit — disconnects the connections (their transactions are rolled back) and immediately starts a smooth reinit;
Retry reinit, Check again.
The hold is enabled automatically when a reinit is refused because of long transactions. It is released after a successful initialisation, manually, or when the archive grows to reinit_hold_max_segments (1000 segments by default, notification retention_hold_released).
Standard locks the database immediately, without checking. Use it only if you know there are no long write transactions.
First initialisation under load. While the master’s archive is empty, there is no segment to compare against.
With an HQbird 2027.2.24 master node: if the node enabled publication itself and the archive has not changed since then, history begins at the moment publication was enabled. A transaction started later enters the journal from its first change and does not interfere with the smooth method. A transaction started earlier did not enter the journal: the reinit waits for it before locking (6 attempts every 10 s), and the locking step shows its number, connection and user. If it has not finished, the reinit ends with the error reinit_pre_publication_transactions: finish it and retry. The Long transactions page shows such transactions in the Transactions started before publication was enabled table.
If publication was enabled manually, not via the node, or the archive has already changed, the start of history is unknown. In that case the smooth method refuses if any write transaction is open, and the message says that the archive does not yet contain a segment. In this case RCM 2027.2.24 does not open the list but writes what to do in the database’s cell. Choose Standard or retry once Firebird archives the first segment.
With a 2027.5.7 master node, the smooth method refuses immediately on the first initialisation of a database that is currently being written to: long_transactions … segment 0 (0001-01-01T00:00:00Z). For the first initialisation of such a database, choose Standard.
For subsequent reinitialisations the smooth method works as usual (the archive already exists).
Transactions older than publication. Firebird does not write to segments a transaction that started before publication was enabled. If the node enabled publication, initialisation waits (6 attempts every 10 seconds) until such transactions finish; otherwise it ends with the error reinit_pre_publication_transactions listing them. After synchronising a publication that added tables, reconnect the applications, then start the initialisation.
5.5. Speed
When
Speed
Setting
Within the transfer window windows.transfer_window (default 23:00-05:00)
constant
limits.reinit_window_mbps, default 100 MB/s
Outside the window
fraction of the measured disk speed
limits.reinit_day_disk_fraction, default 0.5
The node recalculates the mode every 30 seconds: an initialisation started during the day will speed up on its own at night.
The node measures the disk speed with a test. To repeat the test on the master host:
Initialisation time ≈ database size ÷ speed. Example: 100 GB at 100 MB/s — about 17 minutes of pure transfer; in practice it is limited by the network or the disk.
5.6. Restarting the Firebird replica
A new database on the replica. The file is placed without stopping Firebird. Firebird
will read the new replication.conf block only after a restart. Until then the
replica applies nothing. The RESTARTING REPLICA step shows the wait:
Label
What it means
waiting for a Firebird restart on the replica, it is scheduled for …
the node will restart Firebird itself after the last initialisation (reinit_restart_delay_sec), once the other initialisations have finished
… the restart window is closed, the next one will open at …
waiting for the replica’s restart_window
… the last attempt failed, the next one at …
will retry later
the replica cannot restart Firebird itself: restart it manually
auto_restart: never, or this Firebird also serves the master’s databases
The node restarts Firebird once after a series of initialisations, not after
each database.
To restart manually, click Restart replica Firebird.
The wait ends after any successful Firebird restart or when
the replica has applied a segment newer than the copy.
Re-initialisation on a Firebird that also serves the master’s databases.
The node does not stop such a Firebird itself and refuses with
restart_not_allowed. Start the initialisation again and tick Allow
to stop Firebird for this reinit (-allow-restart on the command
line) — at a time when this Firebird’s connections can be dropped, including
to its master databases. Run such initialisations one at a time per host.
Deleting the old copy (the Remove the old replica checkbox, with HQbird
2027.2.24) also stops the replica’s Firebird, by the same rules. If
the node cannot stop this Firebird itself, it deletes nothing and
refuses with restart_not_allowed: also tick Allow
to stop Firebird for this reinit. If at that time another initialisation is
finishing on the replica or Firebird is restarting, the node deletes
nothing and refuses with engine_busy: the master releases the lock,
retry later.
5.7. Queue and concurrent initializations
One database — one initialization at a time (even for different replicas). The Initialize button is disabled while an initialization of this database is in progress.
The master node enforces limits.max_concurrent_reinits initializations of different databases simultaneously (default 1). The rest wait in the queue; the response contains the queue position.
Do not run your own nbackup -L (or ALTER DATABASE BEGIN BACKUP) on a database during its initialization, and do not start an initialization during such a backup: a database can have only one lock. Initialization checks this and refuses with nbackup backup lock already active.
The queue and current transfers are visible on the Transfer page.
Transfer / queues page
- If a `.delta` file remains after a failure, make sure no backup is running and run `nbackup -N `. Do not delete the `.delta` manually.
5.8. Automatic reinitialization
RCM can reinitialize a database in the NEEDS_REINIT state by itself, only within
a configured window. Disabled by default.
When a database enters NEEDS_REINIT:
Cause
Where it is visible
recurring unrecoverable apply error (PK, UNIQUE, FK violation) — 3 times in a row
replica, replication_unrecoverable_error alert
master database GUID has changed (restore, file replacement)
replica, replication_guid_mismatch alert
the master’s archive no longer contains the segments the replica needs
master
the replica has deleted the old copy for initialization and there is no new copy yet (since HQbird 2027.2.24)
replica, replica_removed_for_reinit alert; master
To enable — Settings → RCM (or rcm.json, the auto_reinit section):
Window: per database → per node → global. "always" — at any time.
Windows are calculated by the RCM host’s clock.
max_concurrent — how many initializations (manual and automatic) may be
running in the cluster for RCM to start another automatic one.
Automatic initialization goes through the same space and GUID checks as
manual initialization. The command author is system:autoreinit.
remove_old_replica_when_short (since HQbird 2027.2.24, the Delete
old replica when short of space row) — disabled by default. If
enabled, automatic initialization sends the Delete old
replica flag (4.4). RCM sends it only if the replica is itself in
NEEDS_REINIT or the master’s NEEDS_REINIT cause names it. For
a replica that is IN_SYNC or LAGGING the flag is never sent. If the node
is an older version, RCM starts the same initialization without the flag.
After changing, restart RCM.
Snooze in the master’s card disables automatic
initialization of a single database for 1 hour, 4 hours, 24 hours or until cancelled. Manual
initialization remains available.
5.9. Errors
Error
Cause
What to do
insufficient disk space on master / on replica, 507
not enough space. During re-initialisation the old copy occupies space until the end
chapter 4.4; on the replica (from HQbird 2027.2.24) — the Remove the old replica checkbox (5.1)
node_too_old (from HQbird 2027.2.24)
the Remove the old replica checkbox is set, but the master or replica node is an old version
upgrade the node as stated in the error text or run without the checkbox
the replica deleted the old copy, but initialisation did not finish
start initialisation again (4.4)
publication_off (from HQbird 2027.2.24)
the master’s publication is disabled or contains no tables with a key
Synchronise publication and initialise (5.1)
long_transactions, “Smooth reinit is waiting for long transactions”
long write transactions are open
5.4
long_transactions, “the master’s archive does not yet contain a single segment”
first initialisation under load
Normal (5.4)
reinit_pre_publication_transactions
transactions started before the publication was enabled
reconnect the applications, retry
duplicate_guid
two master databases with the same GUID
remove the copy; if the NEW GUID step was skipped when promoting to master — -force (chapter 8.4)
license_paused
the master’s fbagent has no licence
chapter 2.8
409 orphaned
the database is outside the master’s scan
chapter 3.8
incompatible_engine
different major Firebird versions
chapter 4.3
target_not_replica
a working database sits in the replica’s place (it was made normal)
see below
target_other_replica (from HQbird 2027.2.24)
a copy of another database of this node sits in the replica’s place
see below
restart_not_allowed
the replica’s Firebird also serves master databases
5.6, the “Allow … to stop Firebird” checkbox
fbagent_required
fbagent is not installed on the replica
chapter 1
nbackup backup lock already active
an nbackup backup is in progress
5.7
… -L did not finish in 2m0s and was stopped
nbackup -L on the master did not finish within 2 minutes, so the node stopped it
retry; if the error recurs, check the master’s Firebird (firebird.log)
reinit already in progress for this database
initialisation of this database is already running
wait for it to finish
target_not_replica. A working database sits in the copy’s place: it was made
normal (the file <database>.hqcluster-normal.json exists) or it is not in
replica mode. The node does not overwrite a working database. If it needs to be replaced, a request to the node’s API with
overwrite_non_replica: true (there is no button for this in RCM) will replace the file and keep the old one as
<database>.pre-reinit-<UTC time>.fdb.
target_other_replica (from HQbird 2027.2.24). The replica places the copy in
<databases.root>/<master id>/<database path>. The master id is unique only within
its own cluster, so two databases can end up with the same path. The replica node
does not overwrite a copy belonging to another of its databases: the error names that database and its
master. The node also recognises a copy whose path is recorded differently (a symbolic link or
junction in the path, a short Windows folder name). overwrite_non_replica does not clear this error. Move one of the
copies to another folder or remove that database from the replica, then start
initialisation again. The node sees only its own databases: two replica nodes on
the same host must have different replica folders (databases.root).
5.10. How to check the result
Databases: the master — replica pair in the group is Ok, state
IN_SYNC.
Verify in the master’s card: the nodes count the rows of the tables from
the database’s table list (chapter 3.1) on the master and on the replica and compare them.
Check during quiet time: with active writes the numbers may differ.
With HQbird 2027.2.24 the result page names each side’s list
(for example, “this database’s own list” or “publication tables
(list not set)”). RCM counts the replica using the master’s list. A table
that is absent from both databases is shown as “not in database” and is not counted as an
error. If no tables were compared, the result is “No tables to
compare”, not a mismatch. If the comparison did not finish within the allotted time,
the result is “Not compared (time limit)”, which is also not a mismatch.
Periodic check (optional): the Data check page,
Turn on for all nodes. With HQbird 2027.2.24 the node applies
the settings immediately, no node service restart is needed: after Save RCM
writes “Saved and already in effect”. Node 2027.5.7 needs the
hqclusternode service restarted, and RCM 2027.2.24 says so.
The nodes compare the row counts themselves when the master and replica are on the same
segment. A mismatch raises the data_mismatch alert; then run
Verify.
A table that the operator has removed from the publication is shown as “not
published”, not as a mismatch.
6. Configuring publication
The publication tells the Firebird master which tables’ changes to write to the segments.
Without it, the replica receives nothing.
6.1. What the publication is
In Firebird 4 and 5, the tables to be replicated are defined by the RDB$DEFAULT publication:
Publication enabled — in RDB$PUBLICATIONS it has RDB$ACTIVE_FLAG = 1
(the ALTER DATABASE ENABLE PUBLICATION command).
Published tables — the list in RDB$PUBLICATION_TABLES.
Firebird writes changes to the segments only for published tables and only
when the publication is enabled. Registering the database (chapter 3) does not
enable the publication. It is enabled by Synchronise publication (6.2).
The master node checks the publication every hour
(limits.publication_check_interval_sec, 3600 by default). If it is
disabled, the node checks it every 2 minutes.
On the Databases page, the master database has an icon:
Icon
Meaning
publication ON
publication enabled
publication OFF
Firebird writes nothing to the segments, replicas receive no changes
publication unknown
the node could not read the state
The Publication off filter shows databases with a disabled or unknown
publication.
If a database with a disabled publication already has a replica, the master raises
the master_publication_off alert.
With HQbird 2027.2.24, the master raises this alert also when it refused to
initialise a database with the publication_off error (chapter 5.1): the publication
is disabled or contains no table with a key. The alert level:
warn — the database has no replica yet: initialisation is waiting for the publication;
serious — the database already has a replica;
info — the operator disabled the publication.
The alert is cleared when the publication is fixed or another
initialisation has started.
6.2. Synchronise publication
Master row: publication disabled
Where to click:
in the master database row on the Databases page. When the publication
is disabled, the button is next to the icon;
on the database page;
for several databases: tick the rows, in the Action list select
Synchronise publication. RCM will send a separate command for each
database.
Confirming publication synchronisation
What the node does (a single transaction):
Enables the publication. If the operator disabled it themselves (6.4), it does not enable it.
Adds to the publication all tables with a key that are not there yet.
Removes from the publication tables without a key and tables that the operator
excluded (6.3).
Disables automatic addition of new tables (EXCLUDE ALL FROM PUBLICATION, then adds the required tables). Only the node defines the
composition of the publication.
Master row after synchronisation: publication enabled
A table with a key — a user permanent table that has a
primary key or an active unique index. System and temporary
tables are not published.
Synchronisation also removes from the publication tables without a key that the DBA added
manually.
If the composition is already correct, the node changes nothing.
When the node refuses:
Code
Reason
no_publications
HQbird 2.5/3.0 (6.6)
not_master
the node is not the master
reinit_in_progress
initialisation of this database is in progress
orphaned, database_failed, file_missing
the database is outside scanning, in error, or has no file
All node databases at once — from the command line only. On the Commands
page the result is shown per database: done, skipped or error.
Databases in the FAILED or SEEDING state and databases without a file are skipped.
The same from the command line
Command
hqbirdrcm setpublication -node node-a -db <db_id> # one databasehqbirdrcm setpublication -node node-a # all node databases
The command waits up to 5 minutes and prints a line for each database. On error the exit
code is 1. -nowait — do not wait for the result.
6.3. Publication tables
The “Publication tables” page
Open Publication tables in the master database row.
The page shows:
the publication state (on/off, disabled by operator) and the counters;
each table: name, key and state.
State
Meaning
published
changes go to the segments
not yet published
a table with a key, will be added on synchronisation
excluded
the operator removed it from the publication
no key
cannot be published
In the key column — the primary key, or, if there is none, the unique index with
the smallest number of fields.
Why a table without a key cannot be published. The replica looks up the row for
UPDATE and DELETE by key. Without a key it will not find the row. Add a
primary key or a unique index, then synchronise the publication.
Exclude from publication / Return to publication:
Tick the tables.
Click Exclude from publication or Return to publication.
The node saves the list and immediately synchronises the publication.
Confirming “Exclude from publication”
The list of excluded tables is stored on the master node. Synchronisation does
not change it. When a replica is promoted to master (chapter 8), the list moves to
the new master.
Check (chapter 5.10) shows an excluded table as “not published”,
not as a discrepancy.
6.4. Enabling and disabling the publication
On the Publication tables page: Disable publication /
Enable publication.
Disabling is the operator’s choice. Synchronisation does not
re-enable the publication.
Changes made while the publication is disabled (or while a table is
excluded) are not sent to the replica, even after it is enabled.
After enabling, click Check (chapter 5.10). If the data
diverges — reinitialise the replica (chapter 5).
6.5. A new table
A new table does not get into the publication by itself: the node disables
automatic addition.
After DDL:
Create a primary key or a unique index on the table.
Click Synchronise publication.
Ask the applications to reconnect if reinitialisation is needed. Firebird
does not write to the segments transactions that started before the publication was enabled;
COMMIT RETAINING keeps such a transaction open. Initialisation waits for
such transactions and then fails with reinit_pre_publication_transactions
(chapter 5.4).
A new table in the “not yet published” state
Rows written to the new table before synchronisation will not reach the replica.
If there are any, check the data and, if necessary, reinitialise the replica.
6.6. HQbird 2.5 and 3.0
HQbird 2.5 and 3.0 have no publications. Firebird writes segments if the
replconf plugin file contains a master block. The publication buttons on such nodes are hidden,
and the API responds with no_publications.
The set of tables is defined by the engine parameters:
Parameter
Meaning
include_filter
which tables to replicate: names or patterns separated by commas; empty — all
exclude_filter
which tables not to replicate
The parameters are changed in Settings → Replication parameters (chapter 7.1). The
Publication tables page shows them read-only, with a link Change
in engine settings. Firebird reads the new values after a restart.
Publication tables on HQbird 3.0: engine filters
The replconf plugin. The node writes its own replconf.hqcluster.hqbird file in the
Firebird folder. Firebird reads it only when replconf.properties points to
it. The plugin must be activated once:
Settings → Nodes, the Replication plugin (HQbird 2.5 / 3.0) block. The block
shows where replconf.properties points and the problems that the node
found.
Plugin not activated: replconf.properties points to the HQbird DataGuard file
Activate… The window lists what the node will do: install the plugin,
point replconf.properties to the node’s file, migrate the entries of the old file.
Choose when: Only within the node restart window or Now, ignoring
the restart window.
Plugin activation window
After the Firebird restart, the Activated field shows “yes: the engine
reads the node’s file”.
Plugin activated
Activation restarts Firebird and affects all databases of this Firebird.
Perform it during a quiet period.
7. Other replication options
7.1. Replication parameters
Settings → Replication parameters, wizard form
The Settings → Replication parameters page changes the keys in
replication.conf for the selected databases or for the node as a whole.
Add master and replicas — select the databases. RCM groups them by
Firebird version and role: a separate form for masters and for replicas.
For each parameter, choose an action:
Action
What it does
no changes
the value is not changed
set value
a new value
reset (to the next level)
remove its own value, take the value from the level above
do not write (Firebird value)
the key is not written, the Firebird value applies
Choose where to apply it: To the selected databases or As the default
for their nodes.
Preview — the nodes check the values without changing anything.
Preview of changes
Apply. RCM sends the command to each node.
Where the value comes from (the Current column):
Source
Value
this database
set for the database
node value
set as the default for the node
built-in node value
the node value from the code
Firebird value
the key is not written
from file (not yet set here)
the value from replication.conf, RCM has not changed it yet
set by the node
read-only (paths, prefixes)
A node that is not responding shows its databases as unavailable for selection.
Changes require fbagent (otherwise fbagent_required).
Who restarts Firebird (Firebird reads replication.conf only at
startup):
Node
Who
master
you restart it: the master never restarts Firebird itself
replica with firebird.auto_restart: never
you
replica whose Firebird also serves the master’s databases
you
other replicas
the node restarts it in its own restart window
For a manual restart, the page has a Restart Firebird button.
7.2. Main parameters
Master, Firebird 4/5:
Parameter
Label in RCM
Node value
Firebird
Tip
journal_archive_timeout
Archive timeout
10 s
60 s
how many seconds Firebird waits before closing an incomplete segment. Lower — the replica is closer to the master. Must be less than limits.data_check_quiet_sec (90)
journal_segment_count
Number of segments
64
8
how many segments can reside in .ReplLog. Must be greater than limits.backlog_critical (48)
journal_segment_size
Segment size
—
16 MB
from 1 MB to 512 MB; the receiver will not accept more than 512 MB
buffer_size
—
1 MB
The node also writes log_errors = true (cannot be changed) and
disable_on_error = true.
Replica, Firebird 4/5:
Parameter
Label in RCM
Firebird
Value
apply_idle_timeout
Idle pause
10 s
pause when there are no new segments
apply_error_timeout
Pause after apply error
60 s
pause before retrying after an error
verbose_logging
node: true
verbose replication.log; not recommended to disable
HQbird 2.5/3.0 — log_* keys with the same meaning: log_archive_timeout,
log_segment_count, log_segment_size (not less than 2 × buffer_size). The
alert_command key is set only in node.json.
A hint for each parameter is available in the RCM form.
7.3. Archive storage
The <database>.LogArch archive on the master is cleaned up in stages:
Segments that have been applied by all replicas and that are older than
retention_days.
If free space is less than free_space_floor_gb — applied segments
younger than the retention period. Alert disk_serious_cleanup.
If space is still low — unapplied segments, starting with the oldest.
The replica receives NEEDS_REINIT, alert
replication_paused_reinit_scheduled.
Parameter (Settings → Nodes, Storage and files)
Default
limits.retention_days — Archive retention, days
2
limits.retention_min_kept_segments — Always keep the last segments
0 (disabled)
limits.free_space_floor_gb — Minimum free space
1 GB
Settings → Nodes, “Storage and files”
Clean up the archive manually:
Command
hqbirdrcm cleanuparchive -node node-a # stages for all databases on the nodehqbirdrcm cleanuparchive -node node-a -db <db_id> # a single database
-orphaned (only together with -db) deletes all segments of the database in the
ORPHANED state (chapter 3.8). For any other database the node will respond not_orphaned.
Never run -orphaned on the promotion donor (chapter 8.5).
7.4. Transfer: compression, speed, windows
Compression is set per peer: Settings → Nodes → Peers, column
compress.
Value
Meaning
empty or none
no compression (default)
zstd
zstd compression
The change takes effect immediately. Compression is useful on a slow network.
Segment transfer speed (Settings → Nodes, Transfer and
reinitialization):
Parameter
Default
When it takes effect
limits.channel_a_mbps — Segment transfer speed
50 MB/s
immediately
limits.channel_a_burst_mbps — Segment transfer burst
200 MB
immediately
The unit is mebibytes (MiB), even though the name says “mbps”. The burst cannot be
less than the speed.
Settings → Nodes, “Transfer and reinitialization”
Time windows (Time windows):
Parameter
Default
When it takes effect
What it affects
windows.restart_window — Firebird restart window
master 22:00-05:00, replica always
immediately
when the replica node may restart Firebird
windows.transfer_window — Transfer window
23:00-05:00
after node restart
full initialization speed (chapter 5.5)
The label next to each field shows when the change takes effect: immediately or
node restart.
Settings → Nodes, “Time windows”
7.5. Data verification
Verify — a one-off comparison of the row count on the master and the replica
(chapter 5.10).
Data verification — a periodic comparison (chapter 5.10). The node performs the comparison
when the master and the replica are on the same segment.
With HQbird 2027.2.24, verification settings take effect immediately after
Save; restarting the node service is not required. RCM displays “Saved and already
in effect”. After enabling, the first verification runs after one interval. After
disabling, a verification in progress is interrupted and writes nothing. The new
interval is counted from the end of the last verification. Keep, days, Query
limit, Quiet and Progress generator take effect from the next
verification.
Node 2027.5.7 reads these settings only at startup: after
Save, restart the hqclusternode service on that node. RCM
2027.2.24 displays “Saved, but not yet in effect” and states the reason.
Which tables to compare is defined by the database’s table list (chapter 3.1). With HQbird
2027.2.24, each database can have its own list: the field at registration or the
Synchronization tracking tables block on the master’s database page
(chapter 3.3). The Data verification page shows which list
was used, and the number of tables “not in the database”. In 2027.5.7 the list is per node
(sync_tables).
Tables excluded from publication are shown as “not published”
(chapter 6.3).
Data verification page
7.6. Alerts
Alerts page
The Alerts page. Actions:
Acknowledge — the alert remains visible but is marked acknowledged;
Mute for 60 min — hide for an hour;
Delete / Delete all with this code — RCM passes the deletion to the node
that raised the alert. If the cause remains, the alert will appear again.
Command
hqbirdrcm clearalerts -code backlog_warn # also -id, -acked, -all
As of HQbird 2027.2.33, RCM sends alerts to Telegram, to a webhook (Slack,
Teams, JSON) and by e-mail. The channels are configured in the notify.channels
section of the rcm.json file. The Notification channels block on the
Alerts page shows the channels and sends a test message. RCM reports
problems of level warn and above: a problem has appeared, has become more
serious, or has been cleared. Without channels, RCM sends nothing. Earlier
versions have no sending: watch the Alerts page or poll the RCM API.
as of HQbird 2027.2.30: Firebird has not answered a database connection for a minute (hang). This also includes a connection that failed to establish due to a timeout; firebird_down is a connection refusal only
master_publication_off
publication is off (chapter 6); as of HQbird 2027.2.24 and after a publication_off failure (chapter 6.1)
replica_removed_for_reinit
as of HQbird 2027.2.24: the replica has deleted the old copy for initialisation, and there is no new copy yet (chapter 4.4)
orphaned_database
database outside scanning (chapter 3.8)
restart_required_after_reinit
the replica’s Firebird needs a restart (chapter 5.6)
data_mismatch
the periodic check found a discrepancy
license_paused
fbagent has no licence (chapter 2.8)
7.7. Pausing shipping
On the Databases page, in the master row: Pause shipping /
Resume shipping. For multiple databases — via the Action list.
Pause shipping confirmationMaster row during a pause
The pause remains in effect until Resume shipping or until initialisation.
The master Firebird keeps writing segments. The .LogArch archive grows: while
the replica is stopped, stage 1 (7.3) does not delete its segments.
A long pause may reach stage 3 and NEEDS_REINIT. Keep an eye on space.
The button is absent if the database has no replica or publication is disabled. The
Pause: no licence icon means a licence-related pause (chapter 2.8); it is cleared
only by a licence.
7.8. Logs
Log
Where
Node
<installation folder>/logs/node-YYYYMMDD.jsonl (/opt/hqclusternode or C:\hqclusternode), 32 MB each, 20 files
Firebird replication.log, firebird.log
paths in node.json: firebird.replication_log, firebird.firebird_log
RCM
Linux: journalctl -u hqbirdrcm
RCM audit
rcm-data/audit.jsonl
Remote node log — the Logs page: select a node and a source
(replication.log, firebird.log, node agent).
8. How to transfer a replica to a regular database
There are two paths:
Path
When
What you get
Turn to normal, 8.1
you need a separate working copy: reports, tests, a failure without a new master
a regular database outside replication
Promote to master, 8.3
the replica should become the new master
a database managed by a companion node with the master role
Neither path can be undone through the interface.
8.1. Make Normal
Replica “Action” list: the “Make Normal” item
Databases, replica side: tick the replica rows.
In the Action list, select Make Normal and confirm.
There is no separate button in the row. There is no command-line command either.
“Make Normal” confirmation
3. The replica node:
- runs `gfix -replica none` (HQbird 2.5/3.0: `gfix -replica {}`). If
the database is busy applying segments, the node puts it into
`single`-shutdown for a few seconds (`gfix -shut single -force 0`), clears the replica mode and
returns it with `gfix -online normal`. **All connections to this database
are dropped**;
- writes the marker file `.hqcluster-normal.json` (time, author, db_id,
GUID);
- starts clearing the `.Incoming` queue (8.2).
4. RCM shows the database in the **Not a replica (normal)** group.
The “Databases” page after “Make Normal”
After this, the database is open for writing.
Remove the replica block from replication.conf. The node removes it on the next
scan, and Firebird reads the file at startup:
Until then, “database is not in replica mode” errors for this database are not
raised as alerts.
The marker file protects the database. Initialization will not overwrite such a database:
it is refused with target_not_replica (chapter 5.9). Deleting only the marker is not enough:
the node also checks the replica mode in the database header. The Delete old
replica checkbox (chapter 4.4) does not delete such a database either.
With HQbird 2027.2.24, while the replica is deleting the old copy of this database for
initialization, Make Normal is refused with reclaim_in_progress:
retry later.
If the database needs to become a replica again — only a new initialization with
overwrite will do. This is done via the node API (overwrite_non_replica: true); there is no such button in
RCM. The old file is saved as
<database>.pre-reinit-<UTC time>.fdb, and the marker is deleted.
8.2. What Happens to Segments
Until the node has scanned the databases, the master keeps sending segments. Every 30 seconds the replica node deletes old segments and keeps only the last 100 (keep_segments).
After scanning, the database record on the replica gets the state ORPHANED. The replica node replies to the master with unknown_database. The master stops sending segments to this replica, stops keeping an archive for it, and re-checks it every 10 minutes.
Other replicas of this database are not affected.
The ORPHANED record can be deleted (chapter 3.8): hqbirdrcm forgetdatabase. The database file itself is not deleted.
8.3. Promote to master
The replica becomes the new master. Its file stays in place, and control
passes to the companion node.
Conditions:
Condition
Rejection
the database is a replica
bad_request
a node with the master role — the companion — is running on the same host (same host label in rcm.json, chapter 2.1)
no_companion
promotion of this database is not already in progress
already_running
there is no initialisation into this database or from its master
reinit_running
RCM does not create the companion node: install it in advance (chapter 1).
How to start:
in the replica row, Promote to master, or in the Action list;
RCM will ask for confirmation and name the companion node.
Confirmation “Promote to master?”
Steps (visible in the replica row, names in English):
No.
Step
What it does
1
TURN TO NORMAL
as in 8.1; skipped if the database is already normal
2
NEW GUID
a new database GUID in place (8.4)
3
EXCLUDE ON DONOR
the replica node (donor) excludes the file from its scan (exclude_paths)
4
ENROLL ON
the companion node registers the file as a master database
5
PUBLICATION SYNC
publication synchronisation; the list of excluded tables is carried over from the old master (chapter 6.3)
6
RESTART DONOR FIREBIRD
restart of the donor’s Firebird, without waiting for a window
7
RESTART FIREBIRD
restart of the companion’s Firebird, without waiting for a window
8
FINALIZE
the donor row becomes Ghost replica; the old master may become Master degraded (8.5)
Promotion steps in the replica row
On HQbird 2.5 and 3.0 there are no publications: the PUBLICATION SYNC step
completes with the text “this engine has no publication”.
Promotion steps on HQbird 3.0 (Windows)
If the donor and the companion use the same Firebird, that Firebird is
restarted: connections to all of its databases are dropped.
If a step fails, the job gets failed with the error text. Fix the
cause and click Promote to master again: completed steps are not
repeated. If RCM restarts during promotion, the job will also become
failed — check the state of the nodes and retry.
Licence. If fbagent on the master’s host has no licence, the master
has paused sending. Promotion is still possible. RCM will warn you:
changes made after the pause began will be lost.
8.4. New GUID
After promotion, the database must get its own GUID. Otherwise the new master writes
segments under the old master’s GUID, and its replicas are rejected with
duplicate_guid.
The NEW GUID step on the node:
gfix -shut single -force 0 — all connections to the database are terminated;
nbackup -L, then nbackup -F without -SEQUENCE;
deletes <database>.delta;
checks the header: new GUID, REPLICATION_SEQUENCE = 0;
gfix -online normal.
Firebird is not restarted. The method works on all versions (2.5, 3.0, 4.0,
5.0).
If the step was interrupted, the node issues the alert newguid_interrupted. The database may
remain in single-shutdown. Repeat Promote to master: the step
will continue.
The step is skipped (the text begins with skipped:) if the donor node is an old
version or the file already has its own GUID.
After a new GUID, the old nbackup chain is no longer suitable. Make a new level-0
nbackup copy.
If the database was created with ADD DIFFERENCE FILE, its .delta is located in a different
place: delete it manually.
8.5. After promotion
Donor record. On the replica node the database remains ORPHANED, the path stays in
exclude_paths, and the .Incoming folder and the label remain. In RCM this is the row
Ghost replica with the buttons Open on new master and Clear.
Donor row: «Ghost replica»
To remove the row, click Clear. This changes RCM only.
To remove the donor record from the replica node, run forgetdatabase.
The file and the .Incoming folder remain. HQbird 2027.2.30 and newer does not
reject the command (mailbox_active), because the donor path is in
exclude_paths. Nodes of earlier versions reject it while the file and the
.Incoming folder are present.
Never run cleanuparchive -orphaned on the donor. The donor and the
companion share the same <database>.LogArch folder. The command will delete the live
archive of the new master.
Old master.
If the donor was its last working replica, RCM sets the old
master to Master degraded and pauses sending to the donor
(“sending paused: … (promotion to master)”). Do not resume
sending to the donor: it already holds a working database. To clear this state,
initialise the database onto another replica.
Old master: «Master degraded», sending paused
Initialisation from the old master to the donor node will be rejected
(target_not_replica): it already holds a working database.
If the NEW GUID step was skipped, the old and new masters have the same GUID.
In that case initialisation from the old master requires -force (chapter 5.9).
After a manual promotion RCM does not turn the old master into a replica of the new
master. Stop the applications on the old master and remove its database from
management (chapter 3.8). For a database described as a service, this is done by Rejoin
(8.7).
New master. Set up a replica for it: replica node, peers (chapter 2),
publication (chapter 6), initialisation (chapter 5).
New master: database with a new GUID, no replica yet
8.6. Planned switchover: checklist
This is the procedure for a manual switchover. For a database described as a service, RCM switches the master itself (8.7). A manual promotion does not check whether applications are writing to the old master. Procedure:
In advance. On the replica host, a companion node with the master role is running, and both nodes have the same host label (chapter 2.1). A node for the future replica is ready for the new master.
Stop application writes to the old master’s database.
Wait until the replica has received and applied everything: Databases → IN_SYNC, no queue.
Check (chapter 5.10): the row counts match.
Promote to master (8.3). Wait for the FINALIZE step.
Check: the database is in the companion’s master list, publication on.
Switch the applications to the new master.
Make an nbackup level 0 copy of the new database (8.4).
Clear the ghost record for the donor row (8.5).
Connect the replica to the new master and initialise it (chapter 5).
Old master: remove the database from management or leave it as an archive (8.5).
8.7. Services: switchover and failover in RCM
With HQbird 2027.2.30, RCM moves the master to another host by itself. To do this, the database is described as a service: one logical database on several hosts. On each host of the service there is a master node and a replica node, and the path to the database file is the same. The service is created on the Services page (from HQbird 2027.2.31) or with the command hqbirdrcm services put -id <id> -file <file>.json.
Action
What it does
Commands
Switchover
planned transfer of the master without data loss. Afterwards the old master automatically becomes a replica of the new master
after a failover, returns the old host as a replica of the new master
hqbirdrcm rejoin -service <id>
Resume
takes the service out of the failed state
hqbirdrcm resume -service <id> -check, then hqbirdrcm resume -service <id>
The same actions are available on the service page: the Switchover…, Failover…, Rejoin… and Resume… buttons.
Automatic failover is off by default. It is enabled for each service separately:
hqbirdrcm policy -service <id> -auto-failover on -max-data-loss 30.
It requires routers. RCM starts a failover only when the master node is silent, the majority of routers cannot see the master’s Firebird, and the replica lag is no more than max_data_loss_sec.
A router (hqclusternode router, Linux) keeps HAProxy on the current master of the service. Applications connect to <router host>:<router_port> and do not change the connection string when a switch occurs.
After a failover, RCM fences the old master (role fenced) once it responds again. Bring it back with the rejoin command.
This site uses cookies to improve your experience and remember preferences.